FactGrid Goes NFDI

Friday week before last, we received the news that so many working groups had been eagerly awaiting: the 4Memory consortium (of historical studies) will become part of the Nationale Forschungsdateninfrastruktur (NFDI), the German National Research Data infrastructure.

This is exciting news for FactGrid, just weeks before its fifth birthday. We will be acting as an official repository for historical data in the upcoming NFDI structure. German projects can now make a good case that FactGrid is the optimal platform for their data.
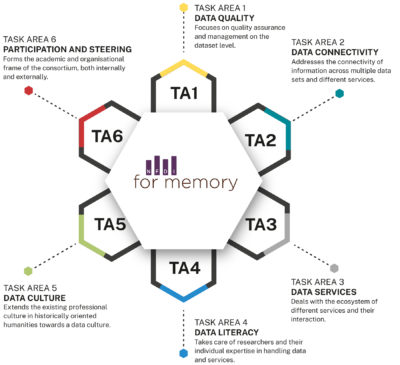
NFDI4Memory task areas

Changing the rules of our present research data management

The German National Research Data Infrastructure aims to bring transparency and sustainability to all research fields, from microbiology to computational linguistics. Whether researchers are still collecting data entirely for themselves in private Word documents and Excel spreadsheets, or whether they are working on digital platforms that are more or less designed like conventional books, designed to be read and looked at – they will face new questions in their research grant applications: Do they produce data? Do they correct publicly available data? If so, the new questions will be: How do they make sure that others can actually work with their data? The idea that new information ends in footnotes of books and articles will not convince the funding institutions any longer. A CSV or JSON data file located on a library server will not do either. Linked Open Data is the only data that is easily reusable – that is what Wikidata has made clear. New platforms are therefore needed – platforms approved by the National Research Data Infrastructure.

The DFG that pushed the process has acted wisely. The different research disciplines had to determine how they would respond to its call for action. They had to create or join umbrella organisations in order to submit proposals for further funding. NFDI4Culture was one of the first groups in the German humanities to receive funding; Text+, for all textual studies, was also among the first arrivals, in 2021. The historical studies collective founded the 4Memory consortium and received the green light in the second round on Friday 4th. Funding will start in March 2023. The Gotha Research Center the 4Memory “participant” on behalf of the FactGrid community in this process.

An international resource as part of a national infrastructure?

It took us a while to feel comfortable with the invitation to participate in this process – back in 2020. At that time we had created a little more than 100,000 items with a handful of participants. Wikimedia Germany was our natural partner. The German National Library was the first major player to collaborate with us in a joint exploration of the Wikibase software. FactGrid from the beginning had invited international collaboration, with projects from France, the United States, Spain, Hungary, and Switzerland. Could we risk a nationalisation of the platform?

The project partners on FactGrid were open to the idea: It would benefit everyone to take the step. The process would open doors to important discussions. We could discuss data standards used worldwide and be able to think of international alliances on this new stage.

Our asset? – Wikibase

Following the NFDI debates,we soon understood why we had been asked to join: We were using Wikibase, the software platform that all members of the nascent consortia were discussing behind the scenes as the very software that could build the bridges between the working groups.

  • Wikibase invites cooperation. Its data modelling is uniquely flexible.
  • Versioning of all editing processes enjoys unprecedented transparency.
  • Wikidata demonstrates that seemingly incompatible fields of knowledge can be managed together in a single graph database.
  • Getting data from a Wikibase platform is as easy as it is to put data into it.
  • Wikibase instances can be federated – we can diversify the scenery without using one single Wikibase instance.

FactGrid was ahead of its time. We were running a functional Wikibase platform while other groups were simply proposing to evaluate the option.

And yet still at the beginning

Over the last two years we have more than quadrupled to 457,000 items. FactGrid is doubling almost every year and there is no reason to believe that this will change in the near future. Projects that are presently preparing data uploads are in the scope of the entire current platform; with our upcoming projects we remain on a global trajectory – we are becoming more international, the platform is learning new languages.

The NFDI process comes just in time because, despite all that growth, we are still right at the beginning, and in urgent need of technological development, which is where we put the focus in our 2020 and 2021 grant proposals. We are not alone in this situation. Wikidata, our elder sister, is still in its initial phase – a peculiar statement, given the fact that Wikidata is celebrating its 10th birthday these days with more than 100 million database objects.

Wikidata is massive. It has rocked the library world as a revolutionary development, but despite that it is still an unknown giant hiding somewhere behind the Wikipedia curtain. Nobody has ever spoken of the data-technical Pentecost miracle which Wikidata actually is. The very name of the project has remained hidden: “Wikidata – you mean Wikipedia, don’t you?”

It is understandable that Wikidata has remained a virtually unknown child. There is neither a search tool leading a wider public to Wikidata information nor is this information readable once you have reached it. The SPARQL query service is a nightmare for normal users. Even if you know how to read computer code– which most of us do not–, how do you find out what information the database can supply? Right, by asking your first specific question with knowledge of the content (the very knowledge that you still do not have). One day an internet-savvy user contacted us with the note that our Query Service had crashed. The Query Service seemed fine; I suggested a video call to get an idea of what the man was seeing on his screen – and it turned out that he was looking at the regular search script. “Send it off, press that blue button!” – He did and received the requested data set. “Ah, I had seen this code stuff but thought it was an error message…”

Wikibase needs two enhancements: An attractive search interface as simple as the Google search box (though with an additional advanced search engine and a SPARQL-search option on top) and browsing software that generates information from the Wikibase or, better still, from several combined Wikibases. The present Wikibase query engine leads you right to the item-pages in the default Wikibase presentation mode, where you can then manually correct or amplify information, but no one seriously enjoys the reading experience. Magnus Manske’s Reasonator, Markus Krötzsch’s SQID, Michael Ringgaard’s KnolBrowser, and Bruno Belhoste’s FactGrid Viewer have shown how Wikibase information can be presented: in pages that present their information concise, well structured, fast to access and easy to exploit. So far, however, all four browsers have remained patchwork solutions. They do not amalgamate platform information in greater depth, and (this is the larger issue) they are as yet not coupled to intelligent search engines. The problem is that we have not yet arrived at independent new resources, at resources whose pages are Google landing points, with pages that amalgamate information from various Wikibases such as Wikidata and FactGrid, and that keep their users on the platform – providing in depth information on request, generating visualisations on the spot, offering downloads of information which users have been accumulating on their tour.

We will get multilingual and attractive Wikibase aggregates. They will integrate information from various resources and they will offer this information in any language requested, identical across all the cultural and political divides. The German NFDI will have to create prototypes of such instruments if they should actually federate Wikibases in a new broader research oriented structure, even if that should start as a national structure.

Opportunities and risks

“The General Intelligence Machine.” Art by H. Lanos for “When the Sleeper Wakes” by H. G. Wells (1899), Wikimedia Commons

The time for a broader research data infrastructure is ripe. Researchers are still handling “their” data on personal hard discs; they copy and paste dates from Wikipedia pages when they could have complete data sets ready to download. Data correction remains fortuitous. Do you write an email to the producers of an online catalogue which you have been accessing with the request to correct a mistake? Do you give the correct date in a footnote of your next article and expect librarians (and Wikipedians) to take note of your work? – We need online resources that allow researchers to correct mistakes right on the screen, in real time; and these resources should be the same ones, which users employ to organise their research. Wikibase is the software that can help to make this possible. How will we get there? Wikibases will have to become the go-to scholarly resources to consult; that is when they will turn into the workbench for the very projects that are using their data.

The landscape of NFDI-consortia comes with its own internal risks. We will need resources to do highly specialised jobs: resources to store and mine texts, resources for the machine readable information which we need in order to make 3D reproductions of objects, and we need resources for historical statements. FactGrid is focusing on this latter need. It cannot become the all-in-one service for historical research. We need the services of other consortia and we should offer our particular services to the other consortia wherever they handle historical statements.

The much more delicate risk of fragmentation looms on the international stage: Will the German expert on French history find herself asked to store her data on a German platform since her funding is German – while her French colleagues with whom she shares the research objects will be delivering their data into a French database? We could, of course, harvest information from 150 national research data infrastructures but that will not provide the same experience for those who generate the information. Working on FactGrid you are about to notice when a colleague in France or China adds to your data. You will contact the colleague with a note of delight about the archival sources that had escaped your notice. Wikibases are joint platforms and should be used as such.

The question of a plurality of national research data infrastructures becomes even more thorny as soon as we look beyond the privileged horizon. We need global platforms to provide equal access to research and to the debates surrounding research. Wikimedia has created Wikidata with the explicit aim of having a software compound on which users from all over the world can work together – accessing and expanding the same pool of global information. We, the international scientific community, the heirs of the international respublica litteraria, shouldn’t fall behind the Wikimedia project.

The fact that FactGrid, an explicitly internationally oriented resource, has entered the NFDI4Memory structure is an interesting development – a chance to get more than one National Research Infrastructure on board.

Links


Header image source: Robert Charles Dudley (British, 1826–1909) Interior of One of the Tanks on Board the Great Eastern: The [Transatlantic Cable] Cable Passing Out 1865/66, Watercolor over graphite with touches of gouache (bodycolor) https://www.metmuseum.org/art/collection/search/383834
A Quarter of a Million Items on FactGrid – just a brief reflection

Germany’s national author Johann Wolfgang von Goethe called it a “masquerade in red and white”, but was himself a member (just as he became a member of the Illuminati a little bit later; it made sense to join such organisations and to know from within what they were all about). Freemasonry was in its most idealistic terms an updated edition of the brotherhood of men united under a simple and strikingly anti aristocratic system: the system of the old craft guilds. With their three degrees of apprentice, fellow and master there was no room for privilege of birth. German masonry evolved from the late 1730’s through the 1750’s principally as a system of four degrees, with Scots Master at the apex and the development did not stop there. The chivalric degrees of the 1760’s and 1770’s gave way to increasingly complex systems, overgrowing this initial construct. These high-degree systems claimed roots in the middle ages if not deeper pasts, synthesising Christianity with alchemy, magic, and theosophy. Masonic entrepreneurs travelled through Europe selling secrets which they would convey in extraordinary lodges. What they offered would have been considered heresies only a generation before, and now became a market of esotericism – a market that turned the masonic world into its first framework and distributor. The Strict Observance or Order of the Temple, the masonic high-grade-system founded by Carl Gotthelf von Hund und Altengrotkau in Germany in 1751 was the biggest player on this stage in central Europe – the system of red and white, the colours of the Knights Templars.

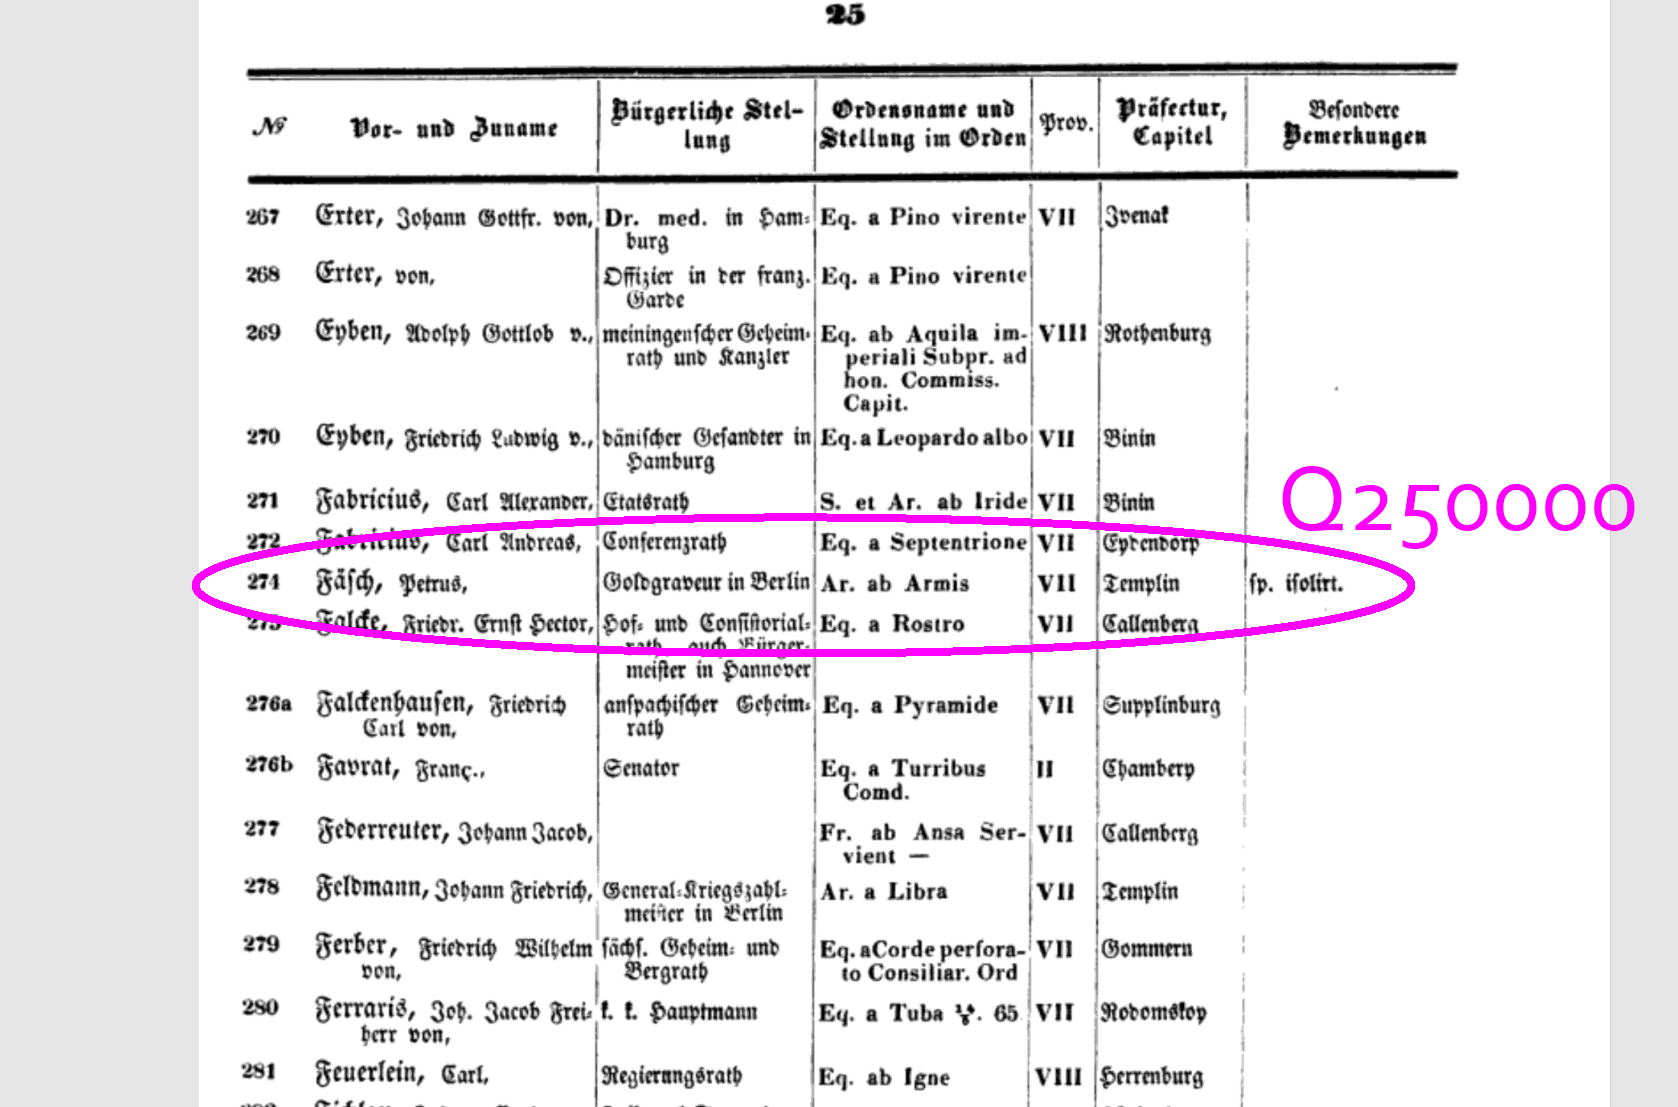
Q250000 is the FactGrid item number of Pierre Faesch, a Frenchman, by profession a gold engraver, who settled in Berlin where he and some of his friends eventually founded their own lodge “Indissolubilis”. He was number 274 in von Lindt’s list of the members of the Strict Observance, published 1846 – number 274 of the 1,266 members he could establish.

Josef Wäges broke the quarter of a millionth item with the input of this list on May 10, 2021 at 7:20 (EST). FactGrid became immediately the most interesting environment for this dataset. 180 of his 1,266 records were old acquaintances: members who already had their Q-numbers on FactGrid. But the new data set which anyone can now create on FactGrid is substantially bigger: it lists 1,595 members with interesting overlaps of projects that have been working on FactGrid over the last three years:

Josef Wäges will publish a more detailed article on the dataset in a lavishly illustrated blog post. The links to the Illuminati are perhaps the most interesting thing to explore in this data set. Von Hund’s claim that the Strict Observance had its roots in the order of the Knights Templar had been both immensely attractive and explosive. The heads of the medieval Order had burned on the stake on May 12, 1310 – but the organisation had gone underground and fused into Scotland’s crypto Catholicism, so the story goes, including the idea that the “Pretender” (to the British throne) was the secret leader of the organisation. The Strict Observance soon expanded from Germany to France, Sweden, Italy, the Baltics and Russia. State leaders became Knights of the Order and met in fancy costumes while members like Goethe or Christoph Bode could easily cast doubts on the historical construct. Von Hund died in 1776 without having given the final proof of the legacy. The organisation itself was by that time in financial troubles over plans to create an insurance system for its members on a foundation of factories, which were to be built under command of the Order on the eve of industrialisation, an organisation that was not really established in the world of modern capitalism.

The internal conflicts culminated in the summer of 1782 when the rank and file of the Observance met at their last convention in the resort of Wilhelmsbad near Frankfurt am Main. The alleged history stood in the centre of the debates and tore the Order apart while a new organisation was secretly emerging behind the scenes: the Order of Illuminati, both as an antithesis and also as a potential heir of the entire infrastructure. They too were by 1782 a masonic high degree system, and they infiltrated lodges far more cunningly from below than from above. With the help of young “Minervals” which they tunnelled from below into the lodges of their interest, and from above with the help of masonic functionaries in the Illuminati leadership. The fascinating thing about the Illuminati was that all the bombastic narratives were handled as little more than a Machiavellian façade by those who acted as “Unknown Superiors” in the hidden centre of this organisation.

Our critical mass: strange organisations of the second half of the 18th century

FactGrid is growing fast. We are doubling our numbers almost every year; that is the more superficial message of the Q250000 jubilee. The more complex message will be: We are (thus far) growing particularly well where we reached our particular critical mass. Entries like Pierre Faesh are the almost ideal subject matter for a Wikibase installation. No portrait has survived, we know little about the biography but we can produce some interesting details with far reaching network information. A genealogy software would not be versatile enough to handle such knowledge. A regular Wiki, with its focus on articles to be written, would on the other hand need to be filled with desolate fragments of repetitive information – we do not know enough to write interesting articles about these people. Using a Wikibase we can easily turn the few points of data we have into an asset. If you want to know more about the “Strict Observance” we can offer the sociological details, networks of the members, family ties, knowledge of the organisation and its surroundings: We can list the various organisational ties of these members and we can – theoretically – give a picture of the landscape of Masonic organisations as they grew and changed from the 17th into the 19th century.

Not quite the software of citizen science: Our Gotha specialisation

At an early point we decided to test the software on the wider audience in a local experiment. Gotha is a small town of some 45,000 inhabitants. We could easily give database courses at the Research Centre. The local project developed with mixed success: Gotha’s Archive of the Lutheran City Church embraced the offer of the free database. Heino Richard of Gotha’s genealogical society entered this project and created its biographical backbone with some 20,000 biographical records linked to the archive’s work and to the city’s history. The integrative appeal remained, however, comparatively weak.

The Wikibase conclusion so far, is interesting in the hands of researchers who are delighted about the flexibility they get with this software. The same tool remains opaque in wider use. We will need interfaces for genealogists and archivists to make broad editing easier, and these interfaces will come.

Novels, religious dissidents, medieval codices and Nazi concentration camps – leaving our comfort zone

We are, nonetheless leaving our comfort zone, the zone of late 18th-century biographies, and this is challenging wherever it leads into fields of information without more comfortable background knowledge:

  • Marie Gunreben of the University of Konstanz has started a project on German novels 1670 to 1750. We have widened this project. We should get the European flow of developments into the picture, the exports and imports, the flow of translations and influences across the European borders. The move is an immense theoretical challenge: We are using a software that creates essential notions of sameness wherever it sets a Q-number. The modern English “novel” should, of course, be the modern French or German “Roman”. But the conceptual equivalents do not really lead us back into the early 18th century. The English “novel” was back then what we will today call a “novella”. Robinson Crusoe, if anything, was a “romance” – a spectacular move in 1719 as the romance had just been pronounced dead, finished by the modern novel(la). How should we handle different conceptual developments in different languages? We are experimenting with set language Items and with Q-items that use the modern conceptual frame as an alleged continuum. It remains to be seen how this will work.
  • Lionel Laborie is about to open the long-expected section on Early Modern religious dissent which our present data have been calling for for the last three years. Freemasons, Rosicrucians and Illuminati, quasi-religious associations built upon a new consensus that their members would leave all their confessional controversies aside and focus on a truth beyond. The result was not exactly deism that shined through all the allusions to God as the master builder and supreme architect. It was rather a competition of increasingly eclectic historical constructs of diverse religious dimensions – of heresies in the old terms of the Catholic or Lutheran orthodoxy and these new orthodoxies emerged within this spectrum with different systems that would not necessarily acknowledge each other. If successful we should be able to eventually give a sketch of the changing map – now with a perspective on the biographies that travelled on this map of ever changing options.
  • Isabella Schwaderer already wrote about her project. She mapped the members of the first two years of the German Schopenhauer Society founded in 1912. The project that began as an experiment led to experiments: Isabel Heide and Martin Gollasch introduced a couple of bigger data sets with the prominent prisoners of Theresienstadt, the map of German concentration camps, and the list of German university academics who signed the declaration of allegiance to the new Regime in 1933. These sets have not yet gained a greater depth of information. They were rather created in order to break the ground for new projects that will discover with a look at early 20th-century networks.

Steps into uncharted territories are a challenge on a Wikibase. You want to augment and to interconnect known objects, you want to work on the basis of our collective present knowledge and suddenly you have to create ever new objects that need ever new objects in order to make sense.

The Middle Ages – the new territory where we will see the biggest growth on our course to Q500000

We will enter new fields and Q500000 is already knocking at our doors. Led by Charles Faulhaber the trilingual PhiloBiblon project has decided to fuse their data into FactGrid – 450.000 items of (late) medieval Iberian books and manuscripts. The project will be a test. We might arrive at the conclusion that the global text production deserves its own Wikibase. It might just as well dissolve the present demarcation lines between archives and libraries on the one hand and historical research on the other. Historical information is in its last consequence not much more than an interpretation of remaining textual and documented evidence. We will bring the evidence and the interpretation onto the same platform.

FactGrid will learn Spanish and Portuguese in the course of this project. The PhiloBiblon group arrives as a team of superbly informed people with different specialisations from data management and librarianship to (literary) history. The technical aim will be to create a user interface on the specific material base that will communicate with the database. FactGrid will act here in the background – nothing to regret, rather the model to go for: The model of a single compound of knowledge that serves various projects as the reservoir of broader collective knowledge.

In the middle of technical developments

Wikibase is not yet a widely used software – it has the potential to become this software. The problem is apparent in any imaginable “normal” use case. You search something – but how do you search anything on the SPARQL Query Service? – on a Query Service that expects you to know what you can search and how you would ask for it – without giving you the slightest hint on either question.

You can use the Wiki surface but here again you will be puzzled. What exactly is the message of these Item pages that collect various statements without order and cohesion? Even if you arrive at a complex item like Q133, Christoph Bode, that item will not tell you half of the story – it does not tell you that this man is the author of hundreds of letters stored in this database, and the recipient of as many – who is mentioned in hundreds of other sources the database has registered.

Markus Manske’s Reasonator gave a glimpse of what one could do with a Wikibase such as Wikidata: One could produce well-structured pages of information automatically in hundreds of languages. The Reasonator did not make it into the software package nor is it easy to use on an external Wikibase.

We will get such browsers – not in the singular but in the plural of general and specific purposes and two of these have entered a test phase last month: Bruno Belhoste’s “FactGrid Viewer” and Michael Ringgaard’s “SLING Browser”. Both seem to do pretty much the same job, but they are doing it differently, opening doors into quite different future developments.

Bruno Belhoste’s FactGrid Viewer (you have been using it over the last minutes wherever you followed the Item-links in this article) is drawing its information straight from the database as you see it. Change data on FactGrid and you will see the new situation with the next browser update. You can switch languages. You get a history of your movements on the site and you get an idea of where you are with a specific item as the object is connected to “what links here?” information.

You can implement Bruno Belhoste’s viewer – pure Javascript – on any website anywhere in the world to see your choice of FactGrid data – the solution for projects who want to use the FactGrid database simply as their database without a further interest in the broader platform.

Michael Ringgaard’s SLING Browser works on the basis of the data dump which FactGrid supplies every evening around 21:15 CET. A new edition of the SLING browser’s presentation of information is created every day. The potential is visible in an intricate detail: The Q-Numbers of SLING browser searches are not necessarily FactGrid Q-Numbers (Christoph Bode our Q133 is on the SLING Browser Q213880). If there is information about the same object available on Wikidata the SLING Browser will give it under the Wikidata Q-Number, and this is only the beginning of the upcoming development: We will eventually see pages that accumulate information from various Wikibases – not in a show of serialised harvests but in a single coordinated representation that accumulates information and that marks the differences only where it arrives at disagreeing statements. This is a tremendous step into the world of “federated Wikibases” that will eventually present the best information of specialised platforms that all speak a common language of triple based statements.

Both browsers are part of the FactGrid-menu-structure but not yet the breakthrough to a simple widespread use of our data. The big issue is at the moment the missing search interface. Google will lead you straight into our items – where you will be lost before you understand how you can navigate on such a platform. The two browsers do not give you a better search interface than the input field on the database’s wiki. If you have just the last name of a person and a rough idea of where they lived that will not help you here or there. You will get to the family name without a hint of how to find those who lived with this Family name. Future Wikibase browsers will have to overcome these dead ends of the individual browsing histories; they will need an advanced search to access data in the first place and internal information that shows why the database has listed the particular object. We will see these interfaces becoming available in a variety of technical options and a broad range of integrations over the next few years.

Integrating FactGrid: NFDI-4Memory participant and GND partner project

We have been surfing a wave of success over the last three years – the wave which Wikibase was creating, the software that is about to be used by national libraries worldwide and in “National Research Data Infrastructures” all over the world.

The reason why National Libraries are experimenting with Wikibase platforms is simple: They have all created authority control data to run the various catalogues that use these data. Humans can understand that Death in Venice was written by Thomas Mann, the 1929 Nobel Prize in Literature laureate. Fresh publications under the same name must have other authors of the same name and this is where databases need a superior form of knowledge. They will handle the 28 authors under that name in a combination of unique identifiers (supplied for instance by the German National Library’s GND’s) and specific biographic background information detailed enough to define who is who in this mess. The system has been working well in its various national boundaries but it was difficult to tell who a specific Thomas Mann was on the BnF’s complementary cataloguing system. It is this riddle that Wikidata has begun to solve. Not only does Wikidata interconnect the up to 300 Wikipedia articles that exist on the various language projects on “the same” entities. The respective Wikidata items will also clarify who these people, organisations and places will be on hundreds of external databases – from the GND to the BnF catalogue.

Historians should states these references on all data they are producing (wherever available) since this is the only way for anyone using their data to automatically check who is who in the different sets they are merging.

The easiest thing FactGrid could do is offer simply all the GND items in the basic pool of objects available on the site to link to. Yet the easiest thing will not be the best thing here. As the National Libraries are about to create and to interconnect their own Wikibases we should enter this compound more as a partner than an interested user. “Our” data should profit from corrections made elsewhere in the wider environment. Corrections made on FactGrid should in return enter the global exchange with information about the research that led to these changes.

We are still living in a world in which DH projects are basically transferring their view of the book world into the new medium of the internet. Books have to be quoted as do web projects – so the common logic, that is creating ever new islands of information on isolated web-platforms.

The future is not the web project quoted in a book or by another web project. The future is in data ready to be downloaded and used in ever new environments. We will need authority to control data, to ensure that those who use our data know what they have downloaded, and we will need collective platforms to offer data in an environment in which the augmentation and further development of information can take place.

https://4memory.de/

It was therefore paramount for us to enter Germany’s present NFDI process. The process is on a trajectory of creating research data repositories in all the fields of the sciences and academic studies – repositories, that will eventually present their data under a broader search engine. We have entered this development as a “participant” of the NFDI’s upcoming 4Memory compound (the compound of the studies that are dealing with historical data).

Our present consideration is how to balance such an integration as a decidedly international site. We will need an international board of FactGrid Stakeholders since this is what we have become over the last three years: an international platform using a multilingual software in order to interconnect research across the borders.