A Quarter of a Million Items on FactGrid – just a brief reflection

Germany’s national author Johann Wolfgang von Goethe called it a “masquerade in red and white”, but was himself a member (just as he became a member of the Illuminati a little bit later; it made sense to join such organisations and to know from within what they were all about). Freemasonry was in its most idealistic terms an updated edition of the brotherhood of men united under a simple and strikingly anti aristocratic system: the system of the old craft guilds. With their three degrees of apprentice, fellow and master there was no room for privilege of birth. German masonry evolved from the late 1730’s through the 1750’s principally as a system of four degrees, with Scots Master at the apex and the development did not stop there. The chivalric degrees of the 1760’s and 1770’s gave way to increasingly complex systems, overgrowing this initial construct. These high-degree systems claimed roots in the middle ages if not deeper pasts, synthesising Christianity with alchemy, magic, and theosophy. Masonic entrepreneurs travelled through Europe selling secrets which they would convey in extraordinary lodges. What they offered would have been considered heresies only a generation before, and now became a market of esotericism – a market that turned the masonic world into its first framework and distributor. The Strict Observance or Order of the Temple, the masonic high-grade-system founded by Carl Gotthelf von Hund und Altengrotkau in Germany in 1751 was the biggest player on this stage in central Europe – the system of red and white, the colours of the Knights Templars.

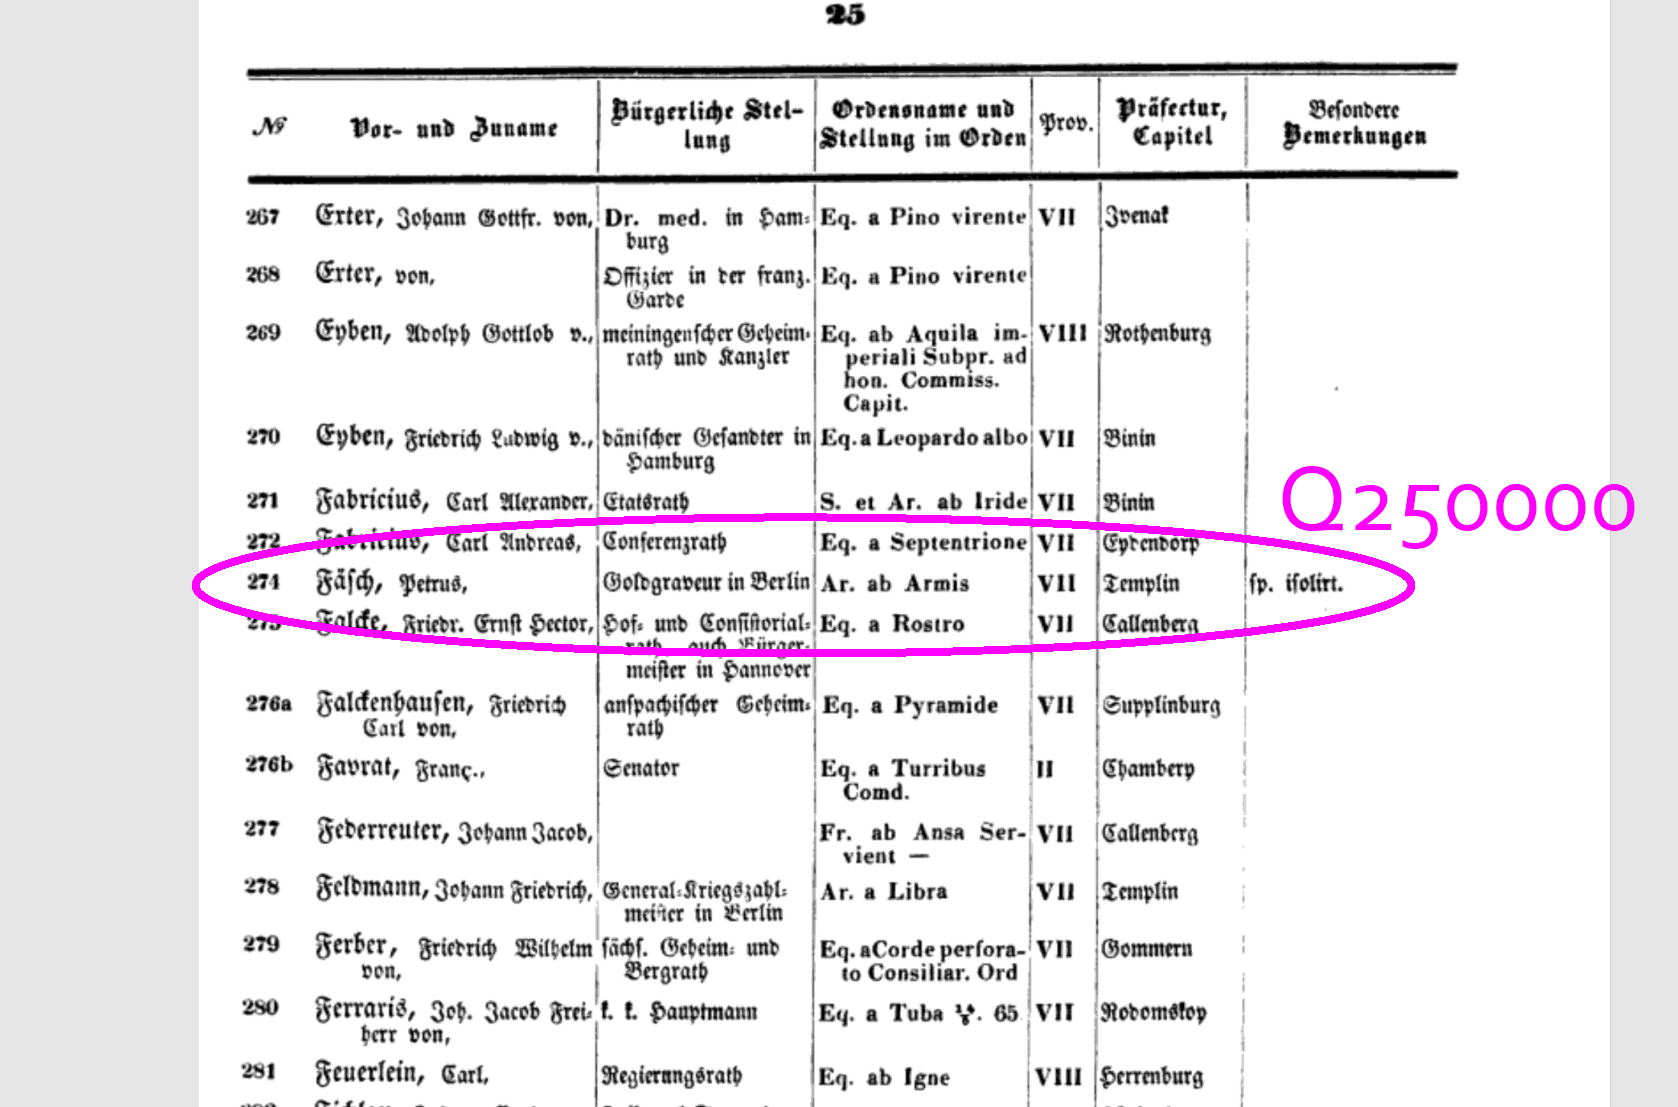
Q250000 is the FactGrid item number of Pierre Faesch, a Frenchman, by profession a gold engraver, who settled in Berlin where he and some of his friends eventually founded their own lodge “Indissolubilis”. He was number 274 in von Lindt’s list of the members of the Strict Observance, published 1846 – number 274 of the 1,266 members he could establish.

Josef Wäges broke the quarter of a millionth item with the input of this list on May 10, 2021 at 7:20 (EST). FactGrid became immediately the most interesting environment for this dataset. 180 of his 1,266 records were old acquaintances: members who already had their Q-numbers on FactGrid. But the new data set which anyone can now create on FactGrid is substantially bigger: it lists 1,595 members with interesting overlaps of projects that have been working on FactGrid over the last three years:

Josef Wäges will publish a more detailed article on the dataset in a lavishly illustrated blog post. The links to the Illuminati are perhaps the most interesting thing to explore in this data set. Von Hund’s claim that the Strict Observance had its roots in the order of the Knights Templar had been both immensely attractive and explosive. The heads of the medieval Order had burned on the stake on May 12, 1310 – but the organisation had gone underground and fused into Scotland’s crypto Catholicism, so the story goes, including the idea that the “Pretender” (to the British throne) was the secret leader of the organisation. The Strict Observance soon expanded from Germany to France, Sweden, Italy, the Baltics and Russia. State leaders became Knights of the Order and met in fancy costumes while members like Goethe or Christoph Bode could easily cast doubts on the historical construct. Von Hund died in 1776 without having given the final proof of the legacy. The organisation itself was by that time in financial troubles over plans to create an insurance system for its members on a foundation of factories, which were to be built under command of the Order on the eve of industrialisation, an organisation that was not really established in the world of modern capitalism.

The internal conflicts culminated in the summer of 1782 when the rank and file of the Observance met at their last convention in the resort of Wilhelmsbad near Frankfurt am Main. The alleged history stood in the centre of the debates and tore the Order apart while a new organisation was secretly emerging behind the scenes: the Order of Illuminati, both as an antithesis and also as a potential heir of the entire infrastructure. They too were by 1782 a masonic high degree system, and they infiltrated lodges far more cunningly from below than from above. With the help of young “Minervals” which they tunnelled from below into the lodges of their interest, and from above with the help of masonic functionaries in the Illuminati leadership. The fascinating thing about the Illuminati was that all the bombastic narratives were handled as little more than a Machiavellian façade by those who acted as “Unknown Superiors” in the hidden centre of this organisation.

Our critical mass: strange organisations of the second half of the 18th century

FactGrid is growing fast. We are doubling our numbers almost every year; that is the more superficial message of the Q250000 jubilee. The more complex message will be: We are (thus far) growing particularly well where we reached our particular critical mass. Entries like Pierre Faesh are the almost ideal subject matter for a Wikibase installation. No portrait has survived, we know little about the biography but we can produce some interesting details with far reaching network information. A genealogy software would not be versatile enough to handle such knowledge. A regular Wiki, with its focus on articles to be written, would on the other hand need to be filled with desolate fragments of repetitive information – we do not know enough to write interesting articles about these people. Using a Wikibase we can easily turn the few points of data we have into an asset. If you want to know more about the “Strict Observance” we can offer the sociological details, networks of the members, family ties, knowledge of the organisation and its surroundings: We can list the various organisational ties of these members and we can – theoretically – give a picture of the landscape of Masonic organisations as they grew and changed from the 17th into the 19th century.

Not quite the software of citizen science: Our Gotha specialisation

At an early point we decided to test the software on the wider audience in a local experiment. Gotha is a small town of some 45,000 inhabitants. We could easily give database courses at the Research Centre. The local project developed with mixed success: Gotha’s Archive of the Lutheran City Church embraced the offer of the free database. Heino Richard of Gotha’s genealogical society entered this project and created its biographical backbone with some 20,000 biographical records linked to the archive’s work and to the city’s history. The integrative appeal remained, however, comparatively weak.

The Wikibase conclusion so far, is interesting in the hands of researchers who are delighted about the flexibility they get with this software. The same tool remains opaque in wider use. We will need interfaces for genealogists and archivists to make broad editing easier, and these interfaces will come.

Novels, religious dissidents, medieval codices and Nazi concentration camps – leaving our comfort zone

We are, nonetheless leaving our comfort zone, the zone of late 18th-century biographies, and this is challenging wherever it leads into fields of information without more comfortable background knowledge:

  • Marie Gunreben of the University of Konstanz has started a project on German novels 1670 to 1750. We have widened this project. We should get the European flow of developments into the picture, the exports and imports, the flow of translations and influences across the European borders. The move is an immense theoretical challenge: We are using a software that creates essential notions of sameness wherever it sets a Q-number. The modern English “novel” should, of course, be the modern French or German “Roman”. But the conceptual equivalents do not really lead us back into the early 18th century. The English “novel” was back then what we will today call a “novella”. Robinson Crusoe, if anything, was a “romance” – a spectacular move in 1719 as the romance had just been pronounced dead, finished by the modern novel(la). How should we handle different conceptual developments in different languages? We are experimenting with set language Items and with Q-items that use the modern conceptual frame as an alleged continuum. It remains to be seen how this will work.
  • Lionel Laborie is about to open the long-expected section on Early Modern religious dissent which our present data have been calling for for the last three years. Freemasons, Rosicrucians and Illuminati, quasi-religious associations built upon a new consensus that their members would leave all their confessional controversies aside and focus on a truth beyond. The result was not exactly deism that shined through all the allusions to God as the master builder and supreme architect. It was rather a competition of increasingly eclectic historical constructs of diverse religious dimensions – of heresies in the old terms of the Catholic or Lutheran orthodoxy and these new orthodoxies emerged within this spectrum with different systems that would not necessarily acknowledge each other. If successful we should be able to eventually give a sketch of the changing map – now with a perspective on the biographies that travelled on this map of ever changing options.
  • Isabella Schwaderer already wrote about her project. She mapped the members of the first two years of the German Schopenhauer Society founded in 1912. The project that began as an experiment led to experiments: Isabel Heide and Martin Gollasch introduced a couple of bigger data sets with the prominent prisoners of Theresienstadt, the map of German concentration camps, and the list of German university academics who signed the declaration of allegiance to the new Regime in 1933. These sets have not yet gained a greater depth of information. They were rather created in order to break the ground for new projects that will discover with a look at early 20th-century networks.

Steps into uncharted territories are a challenge on a Wikibase. You want to augment and to interconnect known objects, you want to work on the basis of our collective present knowledge and suddenly you have to create ever new objects that need ever new objects in order to make sense.

The Middle Ages – the new territory where we will see the biggest growth on our course to Q500000

We will enter new fields and Q500000 is already knocking at our doors. Led by Charles Faulhaber the trilingual PhiloBiblon project has decided to fuse their data into FactGrid – 450.000 items of (late) medieval Iberian books and manuscripts. The project will be a test. We might arrive at the conclusion that the global text production deserves its own Wikibase. It might just as well dissolve the present demarcation lines between archives and libraries on the one hand and historical research on the other. Historical information is in its last consequence not much more than an interpretation of remaining textual and documented evidence. We will bring the evidence and the interpretation onto the same platform.

FactGrid will learn Spanish and Portuguese in the course of this project. The PhiloBiblon group arrives as a team of superbly informed people with different specialisations from data management and librarianship to (literary) history. The technical aim will be to create a user interface on the specific material base that will communicate with the database. FactGrid will act here in the background – nothing to regret, rather the model to go for: The model of a single compound of knowledge that serves various projects as the reservoir of broader collective knowledge.

In the middle of technical developments

Wikibase is not yet a widely used software – it has the potential to become this software. The problem is apparent in any imaginable “normal” use case. You search something – but how do you search anything on the SPARQL Query Service? – on a Query Service that expects you to know what you can search and how you would ask for it – without giving you the slightest hint on either question.

You can use the Wiki surface but here again you will be puzzled. What exactly is the message of these Item pages that collect various statements without order and cohesion? Even if you arrive at a complex item like Q133, Christoph Bode, that item will not tell you half of the story – it does not tell you that this man is the author of hundreds of letters stored in this database, and the recipient of as many – who is mentioned in hundreds of other sources the database has registered.

Markus Manske’s Reasonator gave a glimpse of what one could do with a Wikibase such as Wikidata: One could produce well-structured pages of information automatically in hundreds of languages. The Reasonator did not make it into the software package nor is it easy to use on an external Wikibase.

We will get such browsers – not in the singular but in the plural of general and specific purposes and two of these have entered a test phase last month: Bruno Belhoste’s “FactGrid Viewer” and Michael Ringgaard’s “SLING Browser”. Both seem to do pretty much the same job, but they are doing it differently, opening doors into quite different future developments.
Bruno Belhoste’s FactGrid Viewer (you have been using it over the last minutes wherever you followed the Item-links in this article) is drawing its information straight from the database as you see it. Change data on FactGrid and you will see the new situation with the next browser update. You can switch languages. You get a history of your movements on the site and you get an idea of where you are with a specific item as the object is connected to “what links here?” information.

You can implement Bruno Belhoste’s viewer – pure Javascript – on any website anywhere in the world to see your choice of FactGrid data – the solution for projects who want to use the FactGrid database simply as their database without a further interest in the broader platform.
Michael Ringgaard’s SLING Browser works on the basis of the data dump which FactGrid supplies every evening around 21:15 CET. A new edition of the SLING browser’s presentation of information is created every day. The potential is visible in an intricate detail: The Q-Numbers of SLING browser searches are not necessarily FactGrid Q-Numbers (Christoph Bode our Q133 is on the SLING Browser Q213880). If there is information about the same object available on Wikidata the SLING Browser will give it under the Wikidata Q-Number, and this is only the beginning of the upcoming development: We will eventually see pages that accumulate information from various Wikibases – not in a show of serialised harvests but in a single coordinated representation that accumulates information and that marks the differences only where it arrives at disagreeing statements. This is a tremendous step into the world of “federated Wikibases” that will eventually present the best information of specialised platforms that all speak a common language of triple based statements.

Both browsers are part of the FactGrid-menu-structure but not yet the breakthrough to a simple widespread use of our data. The big issue is at the moment the missing search interface. Google will lead you straight into our items – where you will be lost before you understand how you can navigate on such a platform. The two browsers do not give you a better search interface than the input field on the database’s wiki. If you have just the last name of a person and a rough idea of where they lived that will not help you here or there. You will get to the family name without a hint of how to find those who lived with this Family name. Future Wikibase browsers will have to overcome these dead ends of the individual browsing histories; they will need an advanced search to access data in the first place and internal information that shows why the database has listed the particular object. We will see these interfaces becoming available in a variety of technical options and a broad range of integrations over the next few years.

Integrating FactGrid: NFDI-4Memory participant and GND partner project

We have been surfing a wave of success over the last three years – the wave which Wikibase was creating, the software that is about to be used by national libraries worldwide and in “National Research Data Infrastructures” all over the world.

The reason why National Libraries are experimenting with Wikibase platforms is simple: They have all created authority control data to run the various catalogues that use these data. Humans can understand that Death in Venice was written by Thomas Mann, the 1929 Nobel Prize in Literature laureate. Fresh publications under the same name must have other authors of the same name and this is where databases need a superior form of knowledge. They will handle the 28 authors under that name in a combination of unique identifiers (supplied for instance by the German National Library’s GND’s) and specific biographic background information detailed enough to define who is who in this mess. The system has been working well in its various national boundaries but it was difficult to tell who a specific Thomas Mann was on the BnF’s complementary cataloguing system. It is this riddle that Wikidata has begun to solve. Not only does Wikidata interconnect the up to 300 Wikipedia articles that exist on the various language projects on “the same” entities. The respective Wikidata items will also clarify who these people, organisations and places will be on hundreds of external databases – from the GND to the BnF catalogue.

Historians should states these references on all data they are producing (wherever available) since this is the only way for anyone using their data to automatically check who is who in the different sets they are merging.

The easiest thing FactGrid could do is offer simply all the GND items in the basic pool of objects available on the site to link to. Yet the easiest thing will not be the best thing here. As the National Libraries are about to create and to interconnect their own Wikibases we should enter this compound more as a partner than an interested user. “Our” data should profit from corrections made elsewhere in the wider environment. Corrections made on FactGrid should in return enter the global exchange with information about the research that led to these changes.

We are still living in a world in which DH projects are basically transferring their view of the book world into the new medium of the internet. Books have to be quoted as do web projects – so the common logic, that is creating ever new islands of information on isolated web-platforms.

The future is not the web project quoted in a book or by another web project. The future is in data ready to be downloaded and used in ever new environments. We will need authority to control data, to ensure that those who use our data know what they have downloaded, and we will need collective platforms to offer data in an environment in which the augmentation and further development of information can take place.
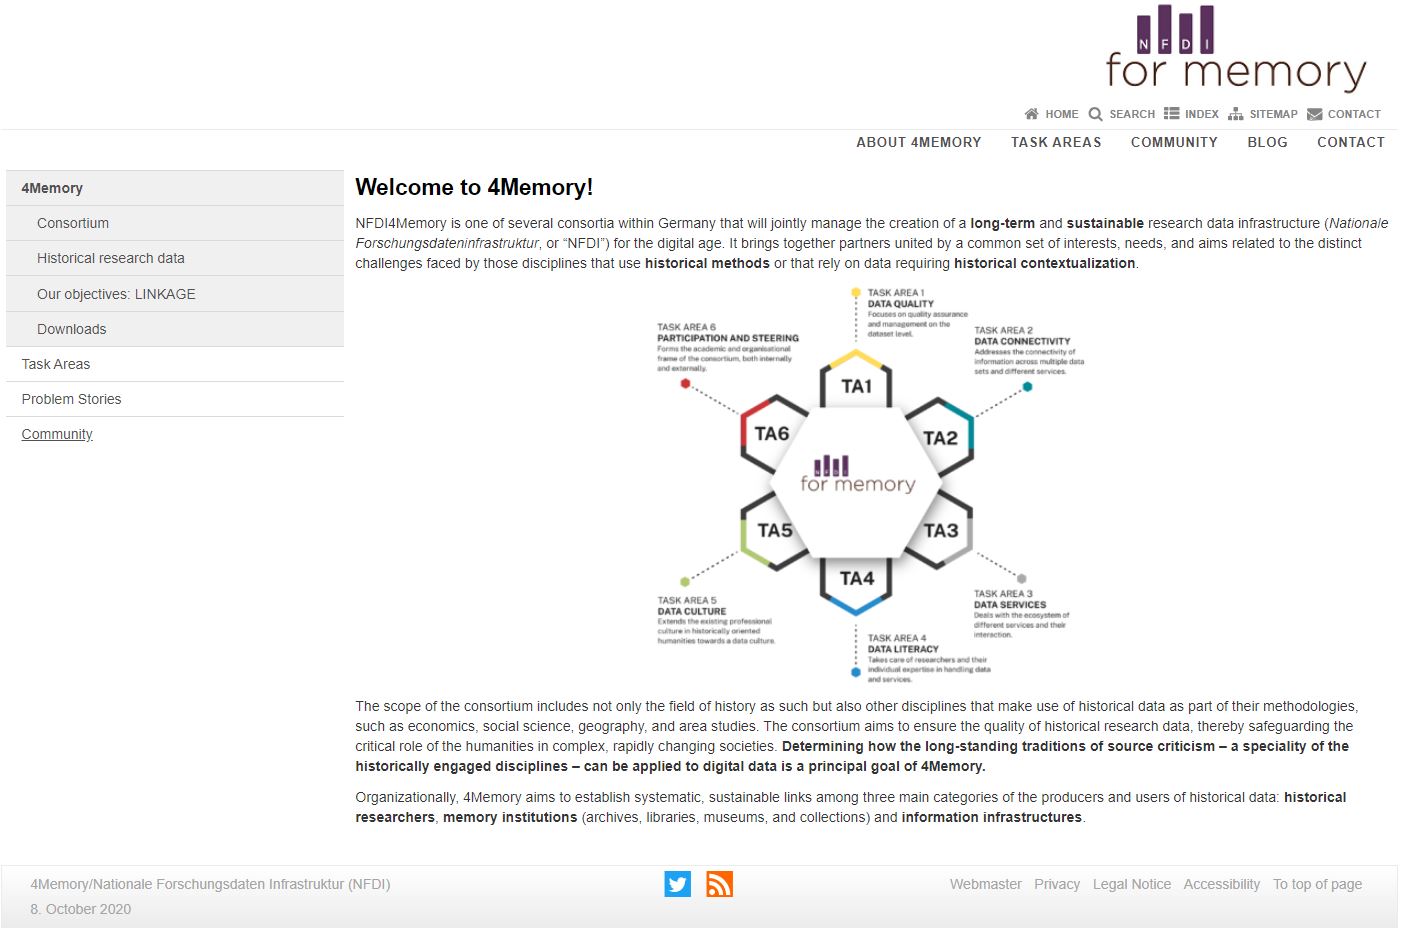
https://4memory.de/

It was therefore paramount for us to enter Germany’s present NFDI process. The process is on a trajectory of creating research data repositories in all the fields of the sciences and academic studies – repositories, that will eventually present their data under a broader search engine. We have entered this development as a “participant” of the NFDI’s upcoming 4Memory compound (the compound of the studies that are dealing with historical data).

Our present consideration is how to balance such an integration as a decidedly international site. We will need an international board of FactGrid Stakeholders since this is what we have become over the last three years: an international platform using a multilingual software in order to interconnect research across the borders.
Die Absolventen des Gothaer Gymnasiums Illustre/ Ernestinum 1524 – 1882

Nach den Pfarrern des Gothaer Territoriums (und ihren Ehefrauen, beidseitigen Eltern, Kindern und deren Ehepartnern – insgesamt gut 15.000 Datenbankobjekten) legt Heino Richard hiermit einen zweiten, quer durch diese Gruppe reichenden Datensatz vor: Die Absolventen des Gymnasiums Illustre Gotha/ Ernestinum.

Primär erfasst sind dabei nach den Listen, die Max Scheider und im Nachtrag Ulrich Lutzkat vorlegten: 4215 Schüler von der Frühphase des am 21. Dezember 1524 gegründeten Gymnasiums bis in den Abschlussjahrgang des Septembers 1882. Von diesen waren uns 872 Schüler bereits bekannt, davon (die Zahlen werden sich ändern, wo immer wir mit den neuen Daten bislang unklare Identitäten auflösen können):

  • 7 aus der Gothaer Illuminatenforschung
  • 21 aus den Gothaer Adressbüchern der Jahre 1828, 1843 und 1846
  • 17 aus dem Gothaer Wählervereichnis von 1849
  • 810 aus dem erwähnten Projekt der Sachsen-Gothaischen Pfarrer

…wobei die Adressbücher uns nach wie vor vor das Problem stellen, dass wir aus ihnen Personen zwar mit Adress- und Berufsangaben aber weitgehend ohne Vornamen bezogen. Die Identifikation kommt hier nur zäh voran.

3343 Personen kamen neu hinzu und zogen dabei 279 neue Väter mit sich, macht unter dem Strich 3622 neue Personen (zwei besonders prominente Neuankömmlinge sind der Absolvent Christian Gryphius mit seinem Vater, dem noch berühmteren Dichter, Andreas).

Die Überlappungen waren ein attraktives Moment des Projektes. Mit jeder von ihnen stabilisierten sich Identifikationen und kamen Hintergrunddaten hinzu, oft zu bislang nur spärlich beleuchteten Personen.

Mit den folgenden beiden Datenbankabfragen werden alle uns bekannten Schüler aufgelistet (es sind derzeit zwei Handvoll mehr, dank einiger bekannter Schüler, die früher abgingen):

Geburtsdaten, Herkunftsorte, Familienbeziehungen, besuchte Universitäten, Berufe…

Wie schon im Fall des Pfarrerbuchs so sind die Daten der Schülerschaft des Gymnasiums Illustre/ Ernestinum, vor alle ein offenes Angebot an die Forschung. Alle erfassten Personen stattete Heino Richard mit Geburtsdaten aus – entweder aus den vorliegenden Quellen oder über eine Rückrechnung (die, wo wir sie vornahmen, durchweg im qualifizierenden Statement zur Genauigkeit der Angabe vermerkt ist; wir gingen dabei von einer 20-Jahres-Differenz als Regelfall aus, das legten die notierten Daten nahe).

Der Artikel der deutschen Wikipedia zum Gymnasium notiert:

Im 17. Jahrhundert wurde das Gymnasium durch Herzog Ernst I. von Sachsen-Gotha-Altenburg weiterhin gefördert. Er bot Söhnen verfolgter Lutheraner aus Ungarn, Schlesien, Polen, Russland und Skandinavien Asyl, die am hiesigen Gymnasium lernten. [abgerufen 2021-04-21]

Das lässt sich nun präzisieren. Skandinavien (sieht man von einigen Dänen ab) erscheint hier nicht, Schlesien und die ehemaligen deutschen Ostgebiete im heutigen Polen sowie, als Randlage, Ungarn jedoch schon (zudem im 19. Jahrhundert auch ein Schüler aus der Karibik). Näher hinein-gezoomt zeichnet sich dann aber das Sachsen-Gotha-Altenburgisch und Coburgischen Territorium ab. Allein 1462 der 4215 Absolventen kamen unmittelbar aus Gotha, die meisten waren „Landeskinder“, Söhne von Amtsleuten und Pfarrern der Dörfer des Territoriums.

https://tinyurl.com/yezpgqds

Ausgiebig sind Informationen zu Studiengängen, besuchten Universitäten sowie späteren Berufen notiert. Die folgenden Suchen geben die Daten.

Universitäre Fächerwahl, Bubble Chart

Zum großen Reiz von Wikibase-Instanzen gehört, dass man sie gewissermaßen über Ecken durchsuchen kann. Die Frage nach der sozialen Herkunft der Schüler lässt sich damit überraschend zielgerichtet angehen. Unmittelbar sind die Berufe, Bildungswege und Arbeitsverhältnisse der Väter ein Indikator für das jeweilige Elternhaus. Die Mütter sind in der Regel Hausfrauen. Ihr Stand entscheidet sich über den Beruf und die Ausbildung ihrer Väter. Die Fragen lassen sic präzise in die Vernetzung der Information hinein stellen:

  • Familiäre Hintergründe: Berufe der Väter und der Väter der Mütter, Kurzlink

Konsequent erfasst sind die genealogischen Hintergrundinformationen; sie ermöglichten die Suche über Eck. Langzeitvisualisierungen der familiären Netzwerke wären eine Herausforderung. Hier ist vor allem unklar, wie man Datenvisualisierungen im historischen Verlauf gestalten sollte – eine Herausforderung für SPARQL-Könner und Tool-Programmierer.

Einladung an die Bildungsgeschichte sich dieses Zettelkastens zu bedienen

Projekte der Bildungsgeschichte, auf der Suche nach einem ergiebigen Untersuchungsgegenstand sollten hier eine extrem praktische Vorarbeit entdecken. Gothas Gymnasium Illustre/ Ernestinum bietet eine noch weitgehend unerschlossene archivalische Überlieferung von 8,3 laufenden Regalmetern im Thüringischen Staatsarchiv Gotha mit extremer Datendichte – darin finden sich:

  • Dokumente zum Unterricht in den verschiedenen Fachgebieten von Griechisch bis Turnen ab der Frühphase
  • Schulordnungen ab 1641
  • Akten der Lehrer mit Gehaltsinformationen ab 1837 ff.
  • Zeugnislisten der Jahrgänge 1641 bis 1946
  • Informationen über „spezielle Verhältnisse der Schüler“ ab 1837
  • Akten zur Finanzierung des Gymnasiums ab 1772

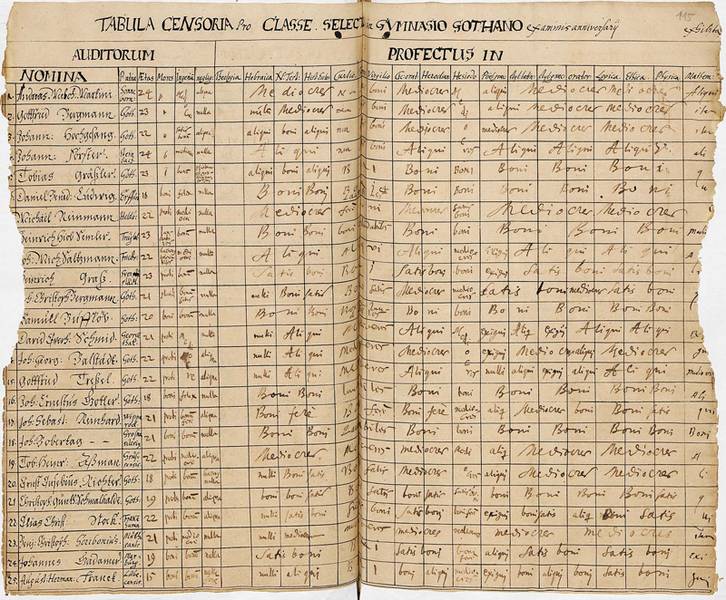
(Hier das elektronische Findbuch zu diesen Beständen.) Spektakulär sind in diesem Bestand die Zeugnislisten mit ihren Beurteilungen der Leistungen im Wandel der Beurteilungskriterien und Fächer. Aus ihnen wird nebenbei ersichtlich, wie die Schule Unterricht organisierte. Man kann mit diesen Listen im Detail Schülerkarrieren – auch die der Schüler, die nicht bis zum Abschluss kamen und uns bislang fehlen – Schuljahr für Schuljahr nachvollziehen.

Zeugnisliste des Gymnasiums Illustre aus dem Thüringischen Staatsarchiv Gotha

Das FactGrid sollte in seinen Datenstrukturen so angenehm frei modellierbar sein, dass es Projekte, die diesen Aktenbestand angehen, anziehen sollte, mit dem Geschenk des fertigen Rasters, von dem aus sich beliebig viel tiefer in die archivalische Datenerhebung einsteigen lässt.


  • Basissuche: einfache Schülerliste: Familienname, Listen-Nummer, GND-ID, Kurzlink
  • Landkartenrepräsentation Geburtsorte der Gothaer Schüler, Kurzlink
  • Besuchte Ausbildungseinrichtungen, Kurzlink
  • Besuchte Ausbildungseinrichtungen, Balkendiagramm
  • Universitäre Fächerwahl, Kurzlink
  • Universitäre Fächerwahl, Bubble Chart
  • Karrieren, Kurzlink
  • Berufliche Positionen, Kurzlink
  • Familiäre Hintergründe: Berufe der Väter und der Väter der Mütter, Kurzlink

The first volume of the Thuringian pastor’s book (1500–1920) as a Wikibase data set

auf Deutsch

In a tremendous effort of a year’s work, Heino Richard of the Genealogical Society of Thuringia e.V., step by step translated the first volume of the Thuringian Pastors’ Books (the volume for the former Duchy of Gotha) into data which we could now feed into FactGrid: More than 13,300 database objects are stemming from this work allowing now entirely new explorations of the territory’s social and religious history. We as curious about the joint ventures this work might inspire. There is no reason to fear that the database version will render all further work on the paper-based volumes obsolete; the platform might, however, offer itself to the editors of the Pfarrerbuch as an unexpected aid.

The eight volumes cover all the parishes of the former Thuringian territories from the Reformation to the 20th century. A first survey is opening each volume with a tour through all the parishes and offices giving the lists of the pastors and auxiliaries who held the respective offices. The main part is in each volume devoted to the individual biographies. Genealogy is key: Pastor after pastor we get the parents with their professions, their wives (with their respective parents and backgrounds), and eventually the children (with information about their professions and the families they married into).

“Things, not strings” – database objects instead of names to be merely spelled out

Translating the volumes into FactGrid-Wikibase data became an ordeal with software’s call for database objects to be connected – where the printed volume was just stating names in various strings of letters. One would have wished to get persistent identifiers with these names since almost all these names reappeared in various contexts – as office holders, as the targets of individual biographies and in various related functions as fathers, sons, sons-in-law or fathers-in-law in the other biographies – without any further clarification of the hard identities behind the mentionings. All this was tricky since names were passed across the whole range from fathers to son, or from grandfathers and uncles to grandsons and nephews to name the closer options that would become most difficult to set apart.

1953 church dignitaries became the stock to start with – almost all connected to more than one of the 142 parishes. The set doubled, tripled and quadrupled with the wives, parents and children and their new relatives to a total of 13,344 data records (as of today). All the records had to be connected to birth and death dates, places, information about marriages, terms of office and occupations.

The entire data is still flawed here and there – it will straighten out the the use it will find. A simple check sheds light into the abyss: We still have some 200 personal data records connected to more than one father and one mother. The double records have sprung unto existence wherever we failed to understand that people were the same – a given name missing or an alternative spelling would render the automatic identification impossible. Things are just as tricky where we supposed that we were dealing with a single person whilst we were actually fusing information of two different lives into a single data record.

Merging data sets remains as painful as the reversal since the software does not take much of an effort to keep track of all the consequences to observe when entire branches of families have been duplicated in the course of the input.

Software features one would love to have

The input of genealogical data calls for a module that understands what basically is. The module should generate family trees and warn you before any input that it has found identical family fingerprints: Children from two families are unlikely to share their birthdays; just as they are unlikely to marry into the same families or to share fathers with the same background data. When entering data, the software should highlight congruent structures and help to merge them with look at the entire overlap which it can track far better than any human eye.

The lack of the stand-alone frontend is even more grievous. Those who want to read the database are not interested in the input pages that list the various triples and qualifiers just as we happened to enter them.

Magnus Manke’s “Reasonator” and Markus Krötzsch’s “SQID” demonstrate what Wikidata and Wikibase should receive: an interface that is solely geared towards the display of data. The next generation of such interfaces will do more than just display the statements made on a single item in a better order. Configurable interfaces will gather information from items referring to your query. It is precarious to list 800 letters and publications of a person you are exploring on the person’s item, if you have already created 800 items for all these titles all with in-depth information on the authors, collaborators, publishers, performances, recipients, archival holdings and so on. It should suffice to note a person’s father and mother on the person’s item — once you start giving reciprocal information on the parents’ pages and siblings you are in the middle of a mess of data which you will inevitably fail to keep in congruence.

Lacking a more cohesive interface it remains difficult to present a data set like this one.

So how can one see what’s in it?

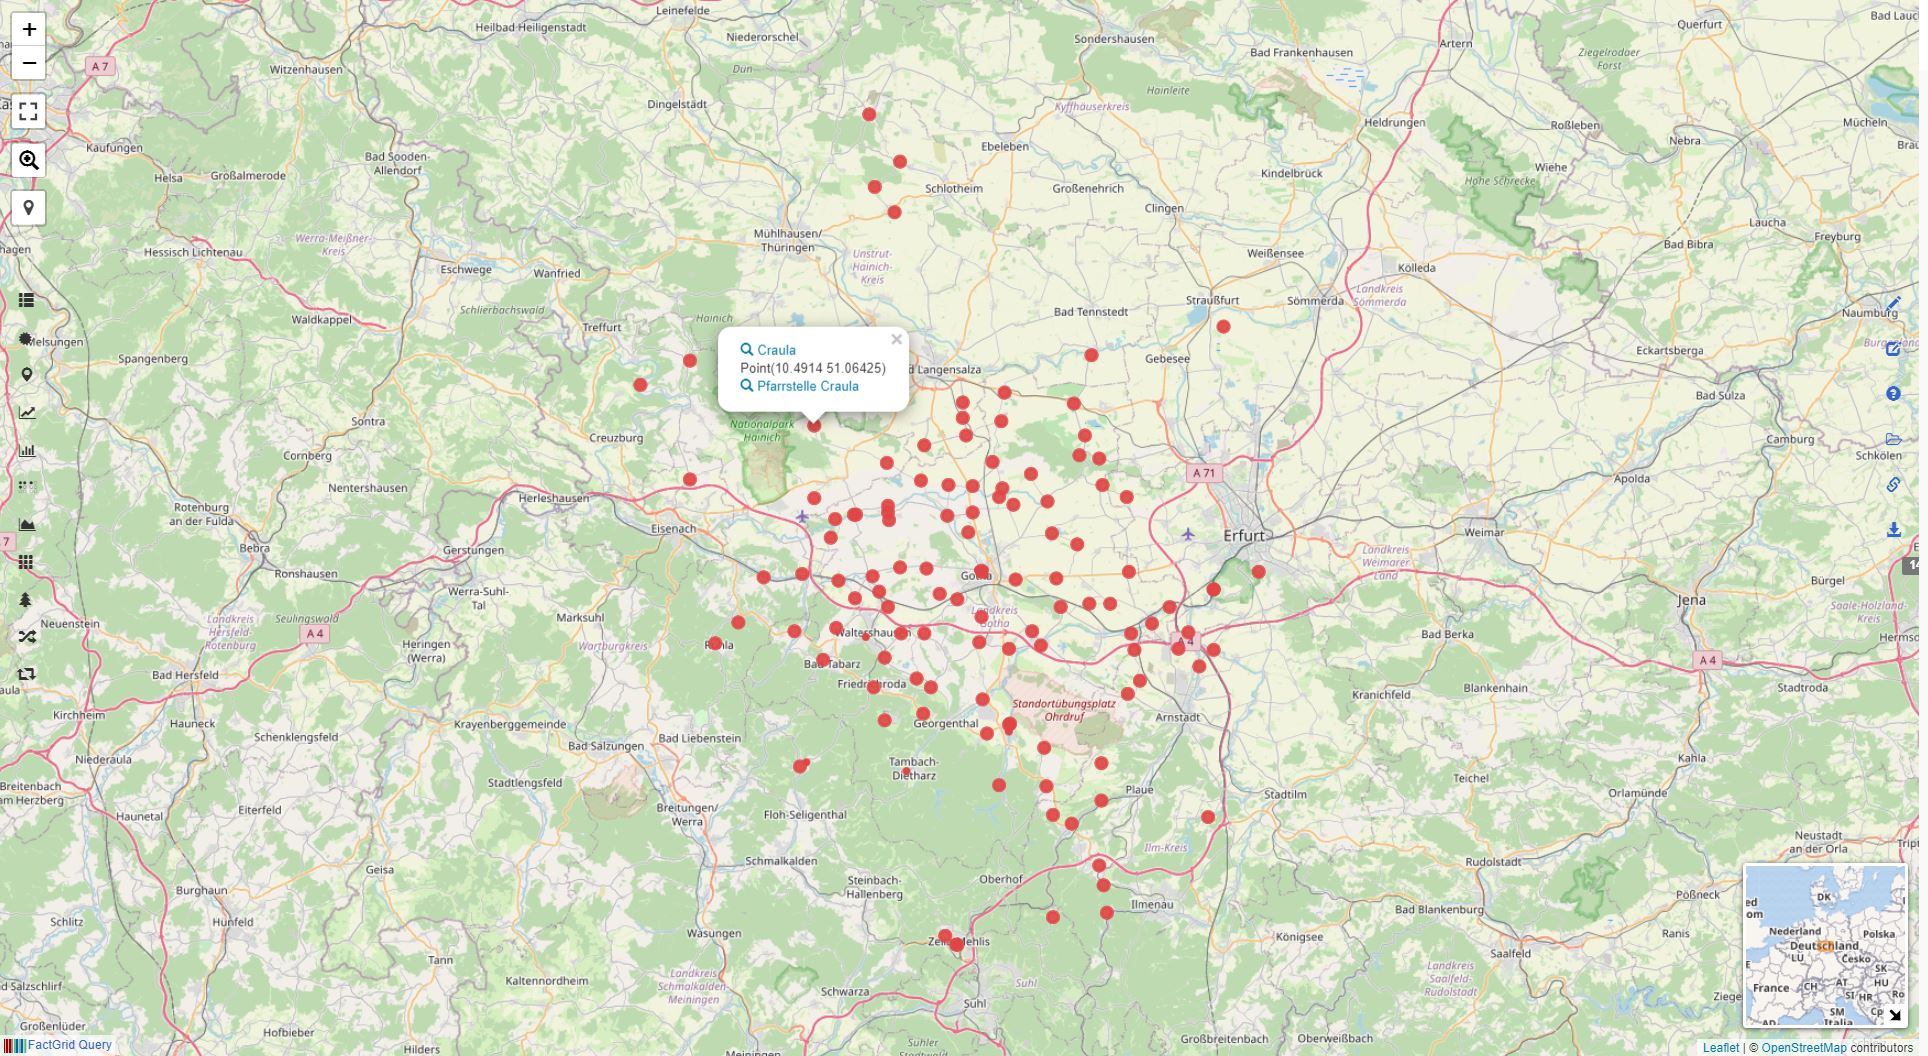
What we can do in the present situation is to give first searches that enable readers to start their own more specific searches – knowing that SPARQL will be a huge put off for the majority of readers. The most practical first search to start with will be the query for all the Protestant parishes of the former Duchy, to appear on a map:

Click the red dots to access to the records of the individual parishes with the lists of pastors registered on the each item.

The table version allows the data to be downloaded as JSON, TSV and CSV data records. TSV, “Table Separated Values”, can be processed in data sheets, whether Excel or Google. The search is sent off with the blue arrow key:

You will have to study an exemplary personal data record before you start your own searches as you need to know how we formulated the triples, i.e. the miniature statements stored in the database, in order to run effective searches as SPARQL queries:

The following query generates a table of all pastors with their birth dates, death dates and parents. With the input help (press the i-Icon to activate it) you can add more table columns to the search in order to get the additional information on children, wives, offices, memberships etc.:

All 13,484 database objects that are using information from the first volume of the Pastors’ Book can be bundled with the P12 (literature) + Q43361 (the first volume of the Thuringian Pastors’ Book) filter.

What is in it to learn?

The Thuringian Pastors’ Book genealogical focus opens up a first interesting perspective: Religion becomes after the territorial decisions of the Reformation increasingly a family institution: You take your religion with you as you receive it at birth. This is even more so with the church hierarchy that evolves. Families become the partners of the territorial churches supplying the students of theology and the pastors for generations. With the database we should become able to ask the more specific questions:

  • What was the exact influence of individual family positions: father, mother, grandfathers, uncles? How did that influence accumulate with more than one pastor in the family?
  • Did the family influence on becoming a pastor decrease over time – with the compulsory education becoming the central provider of professional decisions and career options in the course of the 19th century (and when exactly did such an influence become more noticeable)?
  • To what extent was marrying into a rectory household an advantage – for one’s own career, for the careers of the children?
  • Were local networks as valuable as relationships across spatial distances?
  • To what extent did the ecclesiastical appointments open – geographically? Where did the pastors come from over time?

A project looking for partners

We will have to bring people and institutions together to make our data sets more accessible and the CC0 license is not the threshold here.

(1) It would be an immense gain if could get Wikidata and Histropedia people on board. They are the people who understand the technical side far better than the FactGrid community of the historians; and somehow we should become able to work hands in hands.

(2) It would be a huge win if the resource attracted the team behind the Thuringian pastors books. The software we are using is not really a tool to digest books – it is a tool to facilitate your research. We have the ideal platform one would use to set identifiers and to collect and accumulate information – on the platform with the sources you will not be able to link in the volumes. FactGrid is a team’s tool to be used in the process that prepares a volume.

(3) We would be pleased if we could win the Eisenach State Church Archives for the project. For two years now we have been working with the Church Archive of the City of Gotha, which has started to use the database as its own repository. It would be exciting to widen this project an to get a clearer picture of the whereabouts of archival materials from the 142 parish we have been exploring with this project.

(4) A far broader data networking should add complexity and depth to the work done so far: Our 2000 pastors have written sermons, books, and letters. The Gotha Research Library will keep more of these publications than any other institution. We should be able to match our records to fuse the next layer of networking – the layer of public and private networking via letters and publications into the database with its present genealogical focus. The entire production of books and the links to digitisations is now increasingly done by the VD16, VD17 and VD18 online catalogues and the Kalliope-Database. It would be interesting to connect these records to allow the swift step from personal records to online documents. The Gotha Research Centre will not be able to organise such a projects – it will need partners who adopt the work we did here in a pilot study of the database’s potentials.

If you get interested in the data set and start exploring it, let us know and share your research with us right here on the blog.

Der erste Band des Thüringer Pfarrerbuchs (1500–1920) als Wikibase-Datensatz

English Version

In einer gewaltigen Arbeitsleistung überführte Heino Richard von der Arbeitsgemeinschaft Genealogie Thüringen e.V., Gothaer und Eisenacher Land, im letzten Jahr den ersten Band des Thüringischen Pfarrerbuchs, den Band für das ehemalige Herzogtum Gotha, in eine Version von über 13,300 Datenbankobjekten, die nun ganz neue Auswertungen erlaubt und die vielleicht damit interessante Kooperationen nahelegt. Dass das Datenbankangebot die weitere Arbeit an den Pfarrerbüchern erübrigen wird, steht nicht zu befürchten. Vielleicht aber wird sich das FactGrid den Bearbeitern der Bände als unerwartetes Hilfsmittel anbieten.

Die bisher erstellten acht Bände erfassen von der Reformation bis ins 20. Jahrhundert alle Pfarreien der ehemaligen Thüringer Territorien.

In einem ersten Part sind jeweils die Amtsinhaber nach Pfarreien chronologisch aufgelistet. Ihnen folgen im Hauptteil alphabetisch sortiert die eingehenden Biographien mit extensiven genealogischen Vernetzungen. Notiert werden jeweils die Eltern, die Ehefrauen mit Eltern und die Kinder, nochmals mit Hintergrundinformationen über Berufe, Ehepartner und deren Elternhäuser.

“Things, not Strings!” – Datenbankobjekte statt Namen in Buchstaben

Was in den acht Bänden nicht so schnell sichtbar wird, wurde in der Bearbeitung für das FactGrid zur harten Herausforderung: Wikibase will mit Datenbankobjekten, nicht mit schlichten Namen befüttert sein. Das Thüringer Pfarrerbuch liefert die Namen mit wechselnden Hintergründen (und immer wieder auch variierenden Schreibweisen), doch an keiner Stelle mit stabilen Identifikatoren; und so tauchen dieselben Person jederzeit für sich genommen und in verschiedensten Biogrammen als Väter, Söhne, Schwiegersöhne oder Schwiegerväter auf, ohne dass sogleich klar wird, wer da wer ist. Mit der Datenbankerfassung musste entschieden werden, wann jemand derselbe war – keine einfache Entscheidung, da Namen keine Eindeutigkeit schufen, familiär weitergegeben von Väter an Söhne wie zu Ehren näherer und fernerer Verwandter.

Das Datenvolumen lässt das Dickicht erahnen. Auf die 142 Pfarreien, die zwischen 1500 und 1920 im ehemaligen Territorium bestanden, kamen 1953 Personen als zeitweilige Amtsträger. Mit deren genealogischen Geflechten summiert sich der Personenbestand aktuell auf 13.344 Datensätze, die mit Eckdaten zu Geburt, Tod, Eheschluss und Kindergeburten, Amtszeiten und Berufen auszustatten waren.

Der gesamte Datenkomplex ist noch nicht vollständig konsolidiert. Ein Schlaglicht darauf werfen die Abfragen von Kindern und Eltern: Gut 200 Personendatensätze verfügen derzeit noch über mehr als einen Vater und eine Mutter – Doppelungen zu denen es kam, wenn wir versehentlich unter den Vätern oder Müttern Dubletten anlegten, Datensätze zur selben Person, da erst einmal nicht klar war, dass es sich um dieselbe Person handelte. In anderen Fällen haben Datensätze zwei Mütter oder Väter, da wir bislang verkannten, dass wir hier Biographien hätten trennen müssen – in sie flossen Eltern zweier gleichnamiger, nun zu trennender Personen ein.

Sowohl das Vereinen von Datensätzen wie das Auseinandernehmen sind Arbeiten, bei denen man schnell den Überblick verliert, da die Software nicht erfasst, wo ganze Äste gedoppelter oder zu trennende Information vorliegen und wie mit ihnen am besten zu verfahren ist.

Softwaredesiderate

Für die Eingabe genealogischer Daten wünschte man sich ein Modul, das versteht, was Verwandtschaftsbeziehungen ausmacht, und wie sie in der vorliegenden Datenbank notiert werden. Das Modul sollte Stammbäume generieren und noch im Eingabeprozess warnen, wenn sich familiäre Fingerabdrücke gleichen; es ist unwahrscheinlich, dass Kinder zweier Familien die Geburtstage oder Ehepartner miteinander teilen. Noch bei der Eingabe sollte die Software deckungsgleiche Strukturen aufscheinen lassen und aufzeigen, wie Äste von Information aufeinander zu legen sind.

Unbefriedigend ist bei alledem, dass wir in einer Software ohne stand-alone-Interface arbeiten. Magnus Mankes „Reasonator“ und Markus Krötzschs „SQID“ zeigten, was Wikidata und Wikibase bislang vor allem fehlt: die allein auf die Datennutzung ausgerichtete Oberfläche. Die weiterführende Technologie wird an selber Stelle viel mehr leisten müssen, als Daten aus einem jeweiligen Item besser geordnet wiederzugeben. Interessant werden konfigurierbare Oberflächen, die die Datenbank befragen, und die es erübrigen, Information in ihr gedoppelt abzulegen. Es ist prekär, im Datensatz zu einer Person, sagen wir, 800 Briefe und Publikationen der Person zu listen, wenn man bereits zu diesen 800 Objekten eigene Datensätze anlegte, die weitaus komplexer über Autoren, Beiträger, Adressaten, Verleger, Aufführungsorte, Aufbewahrungsorte, Werkausgaben, Digitalisierte, Transkripte, Übersetzungen und genannten Personen informieren. Im Moment legen wir Informationen doppelt und dreifach ab, allein um im Blick zu behalten, dass sie in der Datenbank vorliegen – mit allen Risiken dabei auseinander laufender Informationsstände.

In der misslichen Lage ist die hiermit vorgelegte Arbeit erst einmal fast nur für Datenfachleute klarer lesbar.

Erste Überblicke und Suchen

Die vielleicht praktischste erste Suche ist die aller protestantischen Pfarrämter des Herzogtums mit der Darstellung auf der Karte:

Jeder einzelne Punkt lässt sich anklicken und birgt den Zugriff auf die Datensätze der Pfarrämter und über diese auf die Amtsinhaber in ihrer jeweiligen Folge.

Die Tabellenversion erlaubt, es die Daten als JSON, TSV und CSV Datensätze herunterzulanden. “Table Separated Values” lassen sich in Datenblättern, ob Excel oder Google Sheets, weiterverarbeiten. Die Suche muss jeweils aktuell mit der blauen Pfeiltaste aktiviert werden:

Es empfiehlt sich, vor jeder weiteren Erkundung einen exemplarischen Personendatensatz zu studieren, um zu erfassen, welche Informationen von uns wie abgelegt wurden – es ist dies das Wissen, das bei jeder SPARQL-Abfrage zum Einsatz kommt:

Die folgende Anfrage generiert eine Tabelle aller Pfarrer mit deren Geburtsdaten, Sterbedaten und Eltern. Mit der Eingabehilfe (das i-Icon aktiviert sie) lassen sich beliebige weitere Tabellenspalten zu Kindern, Ehefrauen, Ämtern, Mitgliedschaften hinzusetzen:

Alle 13.484 Objekte, die den ersten Band des Pfarrerbuchs als Ressource nutzen, lassen jederzeit sich mit der Eingrenzung auf der Literaturangabe bündeln.

Inspiration

Der genealogische Schwerpunkt des Pfarrerbuchs eröffnet eine erste interessanteste Perspektive: Religion ist im protestantischen Raum, mehr als im katholischen, Familiensache. Die territoriale Organisation der religiösen Betreuung findet Pfarrfamilien als organisatorischen Partner. Mit der Datenbankerfassung sollten sich die die härteren Fragen stellen lassen:

  • Wie groß war der spezifische Einfluss von Familienpositionen: Vätern, Müttern, Großvätern, Onkeln?
  • Wie veränderte sich dieser Einfluss? Inwieweit schwand er im Prozess, in dem Bildung klarer eine Angelegenheit der Schulsysteme wurde, die Berufswege unabhängig vom Elternhaus zu ebnen suchen?
  • Inwiefern war die Einheirat in einen Pfarrhaushalt ein Vorteil – für die eigene Kariere, wie die der Kinder?
  • Waren räumlich nahe Vernetzungen gleich viel wert wie Beziehungen über räumliche Distanz hinweg?
  • In welchem Umfang öffnete sich die kirchliche Ämterbesetzung im Verlauf? Wo kamen die Pfarrer her, wie verlagerten sich Herkunftsschwerpunkte?

Projekt auf Partnersuche

Vor allem wird nun die Frage interessant, welche Benutzergruppen wir in Austausch miteinander bringen können.

(1) Ein immenser Gewinn wäre es, könnten wir Geschichtsinteressierte des Wikidata-Projektes und der Histropedia auf den für uns noch durchaus unhandlichen Datenschatz lenken. In beiden Bereichen halten sich die Nutzer auf, die die Technik erst einmal weit besser verstehen als die FactGrid-Community der derzeit etwas über 100 Historiker und Historikerinnen.

(2) Interessant wäre es, das nach wie vor am Thüringer Pfarrerbuchs arbeitende Team für das FactGrid zu gewinnen. Unsere Datenbank sollte sich vor allem als immenser Zettelkasten eignen, in dem sich Informationen ablegen und mit den jeweils aktuellen Quellenbelegen ausstatten lassen.

(3) Freuen würden wir uns, gelänge es uns, das Landeskirchenarchiv Eisenach näher an das Projekt zu binden. Seit gut zwei Jahren arbeiten wir mit dem Kirchenarchiv der Stadt Gotha zusammen, das seinen Aktenbestand im FactGrid verwaltet. Spannend wäre es, zu erfassen, welche Datenbestände aus allen 142 Pfarrämtern heute noch wo liegen. Es ist dies ein im Kirchenarchiv Eisenach soeben koordiniertes Projekt.

(4) Die breite Datenvernetzung wird die bis hierhin getane Arbeit mit Vielschichtigkeit ausstatten: Die von uns erfassten Personen schrieben Bücher und Briefe. Die Forschungsbibliothek Gotha wird von den Publikationen ihres Territoriums mehr als jede andere Institution aufbewahren. Wir sollten hier den wechselseitigen Informationsabgleich zu Wege bringen. Der Abgleich mit dem VD16, VD17 und VD18 und der Kalliope-Datenbestand würde es erlauben, die Datensammlung an die laufende Erschließung von Texten und Dokumenten anzuschließen. Zur genealogischen Vernetzung der Biogramme käme im selben Moment die Vernetzung der jeweiligen öffentlichen Interaktion und persönlichen Korrespondenz. Für die Forschung dürfte es attraktiv sein, mit den Datensätzen Zugriff auf die Digitalisate zu gewinnen, und zu den Personen Texte und Austausch unmittelbar verfügbar vorliegen zu haben.

Wir sind neugierig darauf, wie sich das vorgelegte Datenangebot entfalten wird, und laden dazu ein, Erkundungen der Datensätze noch hier im Blog mit uns zu teilen.

Celebrating FactGrid’s Q100000: Conrad Alexandre Gérard

Silently and without any fanfare we have passed the 100,000 mark on FactGrid! The item in question is a person: Conrad Alexandre Gérard. In a way he is the perfect candidate to mark this occasion. FactGrid has been diving into networks obscure and less obscure, and Gerard travels on both sides of this distinction: The first French ambassador to the United States and a person interested in Mesmerism, the world of miraculous cures based on “animal magnetism” in the 1780s. Our project started with the German Illuminati and spread into Freemasonry. In doing so, it broadened its scope to include France and England. Gerard is again a perfect representative of this outlook: born in Masevaux, France, in 1729 he pursued a diplomatic career that brought him to Mannheim and Vienna and eventually to the young United States of America. If our hopes are fulfilled, we will follow in his tracks and extend ourselves westwards and across the Atlantic over the next year.

Conrad Alexandre Gérard, Philadelphia 1779
The 100.000th item was created by Bruno Belhoste who began to fuse the Francophone Harmonia Universalis database into FactGrid from where the Mesmerism of 1780s and 1790s Paris will now radiate outwards and into the network of its French and continental adherents. J.J.C. Bode brought these spheres into exemplary contact on his journey to Paris in the summer of 1787 – in the journey that marked the end of the Illuminati since he subsequently declined to resume his work as the last active secret superior when he returned home later that year. Mesmerising is the right word – a word derived from Franz Anton Mesmer, who will stand in the centre of the exceptional scene that is unfolding here.

FactGrid was established in order to give historical data a wider outreach and deeper impact. It is living up to its promise. We welcome joint ventures between platforms. We love to give data an additional outreach. We hope that we can give data sets wider connections and place them within unexpected and exciting contexts of research; and we hope that we can bring research teams together on this mission. Wikibase is designed to encourage this mission.

Looking back: we grew much faster than expected

Bruno Belhoste’s (and David Armando’s) project will deserve a longer blog post in 2020; it will take him another two or three months to feed all his data into the database and to be able to offer more substantial and significant insights; the present input is just preparing the basic structures one can then begin to interconnect. The 100,000th item is more of an opportunity to look back and to speak about the future as far as we can see it from our current vantage point.

Collective editing on FactGrid started on June 11, 2018. We began with data from the two Illuminati research projects that have dominated the scene since the late 1990s. The Illuminati will remain a construction site as we hope to bring online the entire “Swedish Box” (the core collection of Illuminati documents as amassed by Bode from 1782 until 1789). Berlin’s Lodge “To the Three Globes” and the Privy State Archive in Berlin have given encouraging signs that they would support the digitisation and detailed cataloguing. We will need three years of public funding for a project of these dimensions.

The Wikibase installation also invited local low-level projects that were open to testing and developing this resource. Would the “citizens” of Gotha be able to work on one and the same platform used by scholars in their wider international projects? Gotha’s City Church Archive was willing to bring its catalogue online on FactGrid. Heino Richard of the city’s Genealogy Association began an enormous project and has already transferred about two thirds of the “Pfarrerbuch”, volume one of the former duchy of Gotha’s pastors, into structured database information. The former duchy’s 140 pastorates are the project’s backbone; more than 2000 pastors filled the positions since the Reformation. The database has linked them to their parents, their spouses, their respective families, and Heino Richard is now on his way to add all the children — work which will eventually comprise over 15.000 data sets. Here is a perfect opportunity for scholarly professionals since we are dealing here with a tight network of families marrying among each other for over five centuries. We will add information about the professions to allow the sociological evaluation of these family ties.

The Illuminati allowed for the database to grow and merge with Freemasonry — after all this was what they were doing in the 1780s: infiltrating lodges in the German speaking territories. Hermann Schüttler had already identified members of some 130 lodges. Christian Wirkner brought his dissertation on Göttingen’s two late 18th century lodges into the database with some 800 biographies which inspired Martin Gollasch to widen the scope with his own research on the beginning of German’s student fraternities. We are now beginning to understand how the “Landsmannschaften” and a wider spectrum of quasi masonic organisations which recruited students in the central Protestant university cities, laid the ground on which the early 19th-century “Burschenschaften” emerged in the years of the Napoleonic wars. Martin Gollasch’s data sets are enriched by information about all the smaller, more intimate circles of friends which traveled through these wider organisations as he has been mining contemporary “books of friends”, the “Stammbücher” in which students collected entries from their dearest friends.

Bruno Belhoste’s and David Armando’s Harmonia Universalis data will widen the spectrum. One thing has already happened with this new project: Bruno Belhoste has effectively turned the entire site into a trilingual project: All our properties are now available in German, French and English. The interface is already speaking Russian and Chinese (and more than 100 other languages), so there remains some work to be done.

We would love to turn Magnus Manske’s Reasonator into the standard — multi-lingual — interface for simply viewing FactGrid data; that, however, will need a bit of more work from different sides.

One of the projects is hibernating at the moment: Tim Herb made it possible to quote the entire (Protestant) Bible on FactGrid down to the level of the individual verses. The central idea was here to connect all the people and places mentioned in the Bible and the Quran and thus to transform the Biblical historicity and genealogy into structured information. The project is daunting: Wikibase allows contradicting statements. How would a database fare with the competing chronologies of modern and early modern historians? Our predecessors saw the Bible with its succinct 6000 years of Universal history since the creation of the world as the ultimate historical source. When they made the comparison to the Greek and Roman sources, it seemed to them as if the pagans had nourished blatant mythologies. How would the project develop if it was widened into the Quran? The Bible and Quran project is an open challenge at this point. Being able to quote the Bible down to the level of verses has, in the meantime, the charm of offering concise intertextual connections: We might develop a new focus on “Early Modern Networks of Religious Dissent”. The protagonists of this scene had their favorites among the Biblical Books — Daniel, the Prophets, the Apocalypse. Collecting the references we should be able to see how the Bible was used by competing groups on their respective missions, so there is potential here.

The shadow of history: All the GND’s Masonic lodges on a map. The former German speaking regions are coming back to life. We have to get beyond this map – and our map should have historical layers.

Our work on Freemasonry is ultimately as much of a challenge: We could theoretically invite lodges from all over the world to map their historical membership lists and their institutional networks of affiliations and systems back in time. FactGrid should allow visualisations of the spread of Freemasonry on timelines and maps. We are presently at about 850 lodges mostly in the former German speaking territories thanks to a test input of GND data, and these data are broadly unconnected so far — an invitation to dream of the far bigger project that could explore Freemasonry as part of early modern globalisation.

…and ahead: a year of massive challenges

2019 was still a year of cautious consolidation. We have grown faster than expected but we remained a platform of projects that worked silently side by side and in a spirit of open-minded friendship, interlocking knowledge here and there. All data on FactGrid is so far hand picked in tremendously time-consuming work. The GND-input should change the work flow and it should invite projects to start right in the middle of publicly available knowledge. Ten million data sets of people, organisations and places will create a landscape ripe for immediate cultivation.

A lot of questions are still open in this project: Shall we include the whole GND in order to operate as a complete DNB-filial project? Our initial idea was to restrict FactGrid to the early modern period but even such self-imposed and somewhat arbitrary limitations were open to later revision. 1900 had been the line we would draw back in 2018. Today we are confronted with ideas to open FactGrid for research on the entire range of data harvested at the German National Library. How could we deal with personal information of living people without the National Library centre that is responding to requests to modify these data? The opposite threat is just as crucial: And how will we make sure that the input (no matter where it ends) does not turn FactGrid into an agglomeration of data that only a few SPARQL-specialists will be able to mine and which we can hardly keep fresh and alive on our site?

We will have to generate a wider community. We will have to advertise the project in the wider field of Wikimedia projects in order to attract fans of open knowledge from Wikidata and from the different Wikipedia history projects. We will need technical help during the input and we will need a community that adopts this mass of data and that transforms the massive mound of date into a vibrant intellectual playground.

As FactGrid is not exactly a grass roots project we will have to make sure that historical research, archives and libraries will see us as a resource and as a site of collective work. If you belong to the wider world of historians, librarians and archivists and if you are interested in big data you should feel challenged by a project that will turn public data into a treasure one can now, all of a sudden, revise, enrich and explore with unprecedented freedom.

The project will need a more solid technical basis on this course. We need an interface to meet the wider public: an interface which anyone can handle without SPARQL. The interface should be multilingual and it will look more like the Reasonator than our present Wikidata-style pages, which want to be edited rather than looked at.

So, some quite daunting challenges ahead – but we expect it to be inspiring to confront and eventually master them. The software is incredibly cool. It has been opening doors to us during its first one and a half years and we have every reason to think that it will continue to demonstrate this potential for the next years. Wikibase is on its way to become the software of a wide network of Wikibase instances and we should try to become a research platform in this network.