In a tremendous effort of a year’s work, Heino Richard of the Genealogical Society of Thuringia e.V., step by step translated the first volume of the Thuringian Pastors’ Books (the volume for the former Duchy of Gotha) into data which we could now feed into FactGrid: More than 13,300 database objects are stemming from this work allowing now entirely new explorations of the territory’s social and religious history. We as curious about the joint ventures this work might inspire. There is no reason to fear that the database version will render all further work on the paper-based volumes obsolete; the platform might, however, offer itself to the editors of the Pfarrerbuch as an unexpected aid.
The eight volumes cover all the parishes of the former Thuringian territories from the Reformation to the 20th century. A first survey is opening each volume with a tour through all the parishes and offices giving the lists of the pastors and auxiliaries who held the respective offices. The main part is in each volume devoted to the individual biographies. Genealogy is key: Pastor after pastor we get the parents with their professions, their wives (with their respective parents and backgrounds), and eventually the children (with information about their professions and the families they married into).
“Things, not strings” – database objects instead of names to be merely spelled out
Translating the volumes into FactGrid-Wikibase data became an ordeal with software’s call for database objects to be connected – where the printed volume was just stating names in various strings of letters. One would have wished to get persistent identifiers with these names since almost all these names reappeared in various contexts – as office holders, as the targets of individual biographies and in various related functions as fathers, sons, sons-in-law or fathers-in-law in the other biographies – without any further clarification of the hard identities behind the mentionings. All this was tricky since names were passed across the whole range from fathers to son, or from grandfathers and uncles to grandsons and nephews to name the closer options that would become most difficult to set apart.
1953 church dignitaries became the stock to start with – almost all connected to more than one of the 142 parishes. The set doubled, tripled and quadrupled with the wives, parents and children and their new relatives to a total of 13,344 data records (as of today). All the records had to be connected to birth and death dates, places, information about marriages, terms of office and occupations.
The entire data is still flawed here and there – it will straighten out the the use it will find. A simple check sheds light into the abyss: We still have some 200 personal data records connected to more than one father and one mother. The double records have sprung unto existence wherever we failed to understand that people were the same – a given name missing or an alternative spelling would render the automatic identification impossible. Things are just as tricky where we supposed that we were dealing with a single person whilst we were actually fusing information of two different lives into a single data record.
Merging data sets remains as painful as the reversal since the software does not take much of an effort to keep track of all the consequences to observe when entire branches of families have been duplicated in the course of the input.
Software features one would love to have
The input of genealogical data calls for a module that understands what basically is. The module should generate family trees and warn you before any input that it has found identical family fingerprints: Children from two families are unlikely to share their birthdays; just as they are unlikely to marry into the same families or to share fathers with the same background data. When entering data, the software should highlight congruent structures and help to merge them with look at the entire overlap which it can track far better than any human eye.
The lack of the stand-alone frontend is even more grievous. Those who want to read the database are not interested in the input pages that list the various triples and qualifiers just as we happened to enter them.
Magnus Manke’s “Reasonator” and Markus Krötzsch’s “SQID” demonstrate what Wikidata and Wikibase should receive: an interface that is solely geared towards the display of data. The next generation of such interfaces will do more than just display the statements made on a single item in a better order. Configurable interfaces will gather information from items referring to your query. It is precarious to list 800 letters and publications of a person you are exploring on the person’s item, if you have already created 800 items for all these titles all with in-depth information on the authors, collaborators, publishers, performances, recipients, archival holdings and so on. It should suffice to note a person’s father and mother on the person’s item — once you start giving reciprocal information on the parents’ pages and siblings you are in the middle of a mess of data which you will inevitably fail to keep in congruence.
Lacking a more cohesive interface it remains difficult to present a data set like this one.
So how can one see what’s in it?
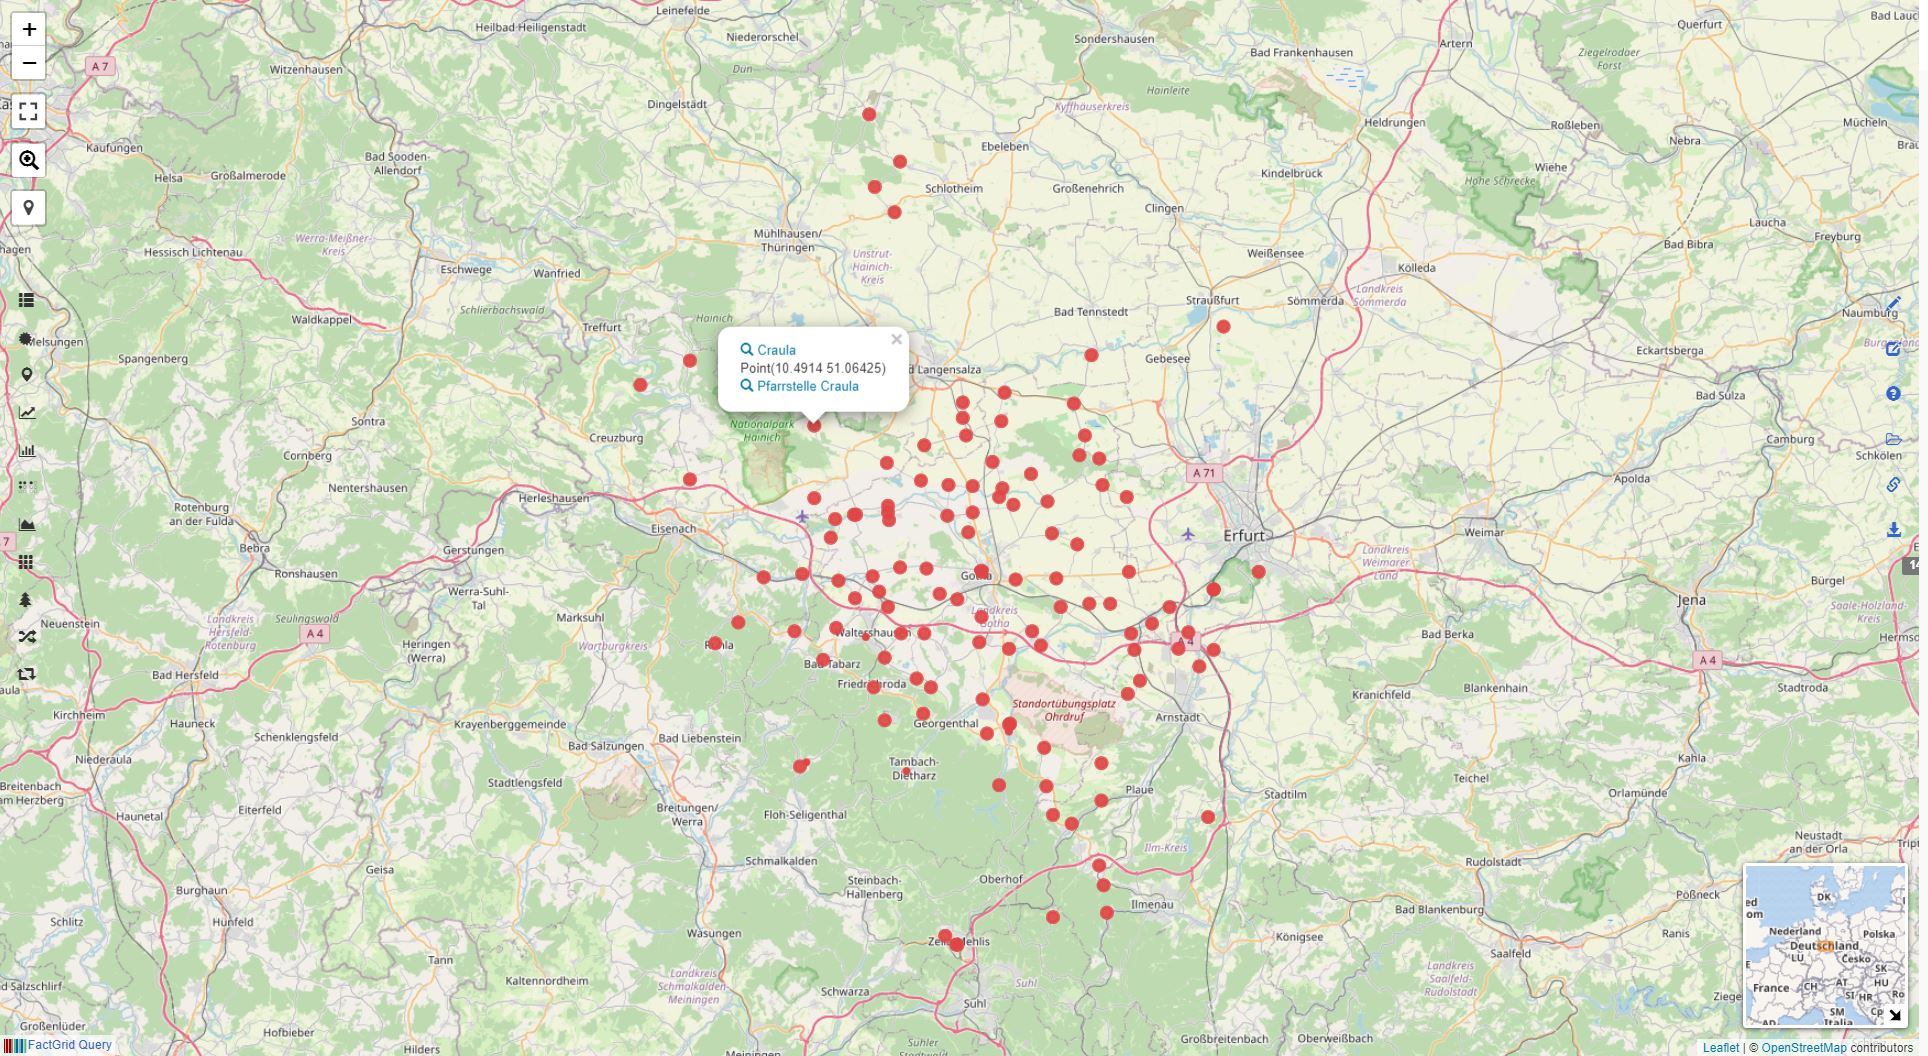
What we can do in the present situation is to give first searches that enable readers to start their own more specific searches – knowing that SPARQL will be a huge put off for the majority of readers. The most practical first search to start with will be the query for all the Protestant parishes of the former Duchy, to appear on a map:
Click the red dots to access to the records of the individual parishes with the lists of pastors registered on the each item.
The table version allows the data to be downloaded as JSON, TSV and CSV data records. TSV, “Table Separated Values”, can be processed in data sheets, whether Excel or Google. The search is sent off with the blue arrow key:
You will have to study an exemplary personal data record before you start your own searches as you need to know how we formulated the triples, i.e. the miniature statements stored in the database, in order to run effective searches as SPARQL queries:
The following query generates a table of all pastors with their birth dates, death dates and parents. With the input help (press the i-Icon to activate it) you can add more table columns to the search in order to get the additional information on children, wives, offices, memberships etc.:
All 13,484 database objects that are using information from the first volume of the Pastors’ Book can be bundled with the P12 (literature) + Q43361 (the first volume of the Thuringian Pastors’ Book) filter.
What is in it to learn?
The Thuringian Pastors’ Book genealogical focus opens up a first interesting perspective: Religion becomes after the territorial decisions of the Reformation increasingly a family institution: You take your religion with you as you receive it at birth. This is even more so with the church hierarchy that evolves. Families become the partners of the territorial churches supplying the students of theology and the pastors for generations. With the database we should become able to ask the more specific questions:
- What was the exact influence of individual family positions: father, mother, grandfathers, uncles? How did that influence accumulate with more than one pastor in the family?
- Did the family influence on becoming a pastor decrease over time – with the compulsory education becoming the central provider of professional decisions and career options in the course of the 19th century (and when exactly did such an influence become more noticeable)?
- To what extent was marrying into a rectory household an advantage – for one’s own career, for the careers of the children?
- Were local networks as valuable as relationships across spatial distances?
- To what extent did the ecclesiastical appointments open – geographically? Where did the pastors come from over time?
A project looking for partners
We will have to bring people and institutions together to make our data sets more accessible and the CC0 license is not the threshold here.
(1) It would be an immense gain if could get Wikidata and Histropedia people on board. They are the people who understand the technical side far better than the FactGrid community of the historians; and somehow we should become able to work hands in hands.
(2) It would be a huge win if the resource attracted the team behind the Thuringian pastors books. The software we are using is not really a tool to digest books – it is a tool to facilitate your research. We have the ideal platform one would use to set identifiers and to collect and accumulate information – on the platform with the sources you will not be able to link in the volumes. FactGrid is a team’s tool to be used in the process that prepares a volume.
(3) We would be pleased if we could win the Eisenach State Church Archives for the project. For two years now we have been working with the Church Archive of the City of Gotha, which has started to use the database as its own repository. It would be exciting to widen this project an to get a clearer picture of the whereabouts of archival materials from the 142 parish we have been exploring with this project.
(4) A far broader data networking should add complexity and depth to the work done so far: Our 2000 pastors have written sermons, books, and letters. The Gotha Research Library will keep more of these publications than any other institution. We should be able to match our records to fuse the next layer of networking – the layer of public and private networking via letters and publications into the database with its present genealogical focus. The entire production of books and the links to digitisations is now increasingly done by the VD16, VD17 and VD18 online catalogues and the Kalliope-Database. It would be interesting to connect these records to allow the swift step from personal records to online documents. The Gotha Research Centre will not be able to organise such a projects – it will need partners who adopt the work we did here in a pilot study of the database’s potentials.
If you get interested in the data set and start exploring it, let us know and share your research with us right here on the blog.